---
title: "Best Browserbase Alternative in 2026 for Protected Web Access"
description: "Zenrows vs Browserbase, benchmarked on four protected targets. Compare success rates, what failed sessions cost, developer experience, and when each tool fits."
---
# Best Browserbase Alternative in 2026 for Protected Web Access
> Zenrows vs Browserbase, benchmarked on four protected targets. Compare success rates, what failed sessions cost, developer experience, and when each tool fits.
Source: https://www.zenrows.com/blog/best-browserbase-alternative-for-protected-web-access
Zenrows is the best Browserbase alternative when you are running protected web access at scale and need the bill to track successful requests rather than browser time. Our testing showed a **100 percent success rate for Zenrows across four protected targets, compared with 62.25 percent for Browserbase**.
Browserbase headless browser infrastructure gives [AI agents](/glossary/ai-agents-and-the-web) the tools to navigate pages, maintain sessions, and handle interactions that a standard HTTP request cannot. But for data extraction, running the browser adds another configuration layer. You manage sessions, waits, retries, concurrency, parsing, and the extraction logic around the browser.
Browserbase also charges for browser infrastructure usage, so failed attempts can still consume resources without producing usable data. **A workload of 10,000 daily page attempts with a 40 percent failure rate costs an estimated $3,499 monthly on Browserbase's $99/month Startup plan, for browser execution and proxy bandwidth alone**. Browserbase Fetch avoids spinning up a browser, but it does not render JavaScript and has proxy use disabled by default, so protected-site requests require you to enable proxies and pay separately for the bandwidth used.
[**Zenrows Fetch**](https://docs.zenrows.com/fetch/api-reference) **uses `mode=auto` to automatically choose the configuration required by the target, and bills only for successful requests**. It also parses the retrieved data into structured JSON without requiring you to build custom parsers around a browser session. For larger workloads, [Batch](https://docs.zenrows.com/batch/introduction) handles URL lists, retries, concurrency, result tracking, and delivery.
If your workflow requires an AI agent to navigate a site, click elements, authenticate, or maintain browser state across multi-step workflows, you can use either Browserbase or [Zenrows Browser](/products/browser).
But if you need to retrieve data from protected websites without operating a browser, Zenrows provides a direct path.
In this comparison, we benchmark both platforms, compare their pricing and developer experience, examine where each fits, and show when switching from Browserbase to Zenrows makes sense.
## Zenrows vs. Browserbase at a Glance
The table below compares Zenrows and Browserbase across anti-bot performance, pricing, key capabilities, and developer experience.
| Metric | Browserbase | Zenrows |
| --- | --- | --- |
| **Anti-bot success rate on protected sites (our test)** | 62.25% at 2 req/s | 100% at 2 req/s |
| **Billing model on failed requests** | Browser and proxy usage is billed based on resources consumed, failed browser sessions can still consume browser time and proxy bandwidth | Bills only successful requests |
| **Entry price** | $20/month (Developer plan) | $16/month (Build plan) |
| **Residential proxy cost** | 1 GB included on Developer plan, then $12/GB, 5 GB included on Startup plan, then $10/GB | Included in usage pricing, 10× credit multiplier |
| **Structured output included** | Yes, Fetch supports JSON and Markdown with Extract | Yes, Markdown, structured JSON, and other response formats |
| **Session management required** | Required for browser-based workflows; Sessions give you direct control over browser state, cookies, authentication, and multi-step interactions; Fetch does not create a browser session | Not required; Fetch manages requests, Browser is also available for persistent browser interaction |
| **Self-service signup** | Yes | Yes |
| **Free plan** | Yes, free plan includes 3 concurrent browsers, 1 browser hour, 3 Agent runs, 1,000 Search calls, 1,000 Fetch calls, and 15 minutes per session | Yes, 5,000 credits per month with 5 concurrent requests |
| **Cloudflare handling** | Fetch does not execute JavaScript and does not provide browser-level protection handling, Sessions API can use browser fingerprinting, proxies, and CAPTCHA solving for protected sites | Built in, `mode=auto` can automatically escalate to protected access when required |
| **DataDome handling** | Sessions API can use Browserbase's infrastructure, including proxies and CAPTCHA solving, but Fetch performed poorly during our testing | Built in, Zenrows handles DataDome through its infrastructure and `mode=auto` |
| **One API key for all features** | Yes, one API key covers Browser, Fetch, Search, and other platform features | Yes, one API key covers Fetch, Batch, and proxies |
## What Browserbase Actually Costs in 2026 vs. What You Expect
Browserbase's time-based billing makes the cost of high-volume web data extraction difficult to predict. You pay for browser session time and proxy bandwidth, so failed sessions still incur infrastructure costs.
Browserbase's $20/month Developer plan includes 100 browser hours, with additional hours billed at $0.12/hour, while the $99/month Startup plan includes 500 browser hours with $0.10/hour overage. Both plans also charge separately for proxy bandwidth, with overage rates of $12/GB on Developer and $10/GB on Startup. These costs are separate from Fetch, Extract, Search, and model-token usage.
At 10,000 page extraction attempts per day on a Cloudflare-protected site with an assumed 40 percent failure rate, the workload consumes about 5,000 browser-hours per month, assuming one minute per extraction, and roughly 300 GB of proxy bandwidth at the 1 MB minimum per session. On the Developer plan, your estimated monthly cost becomes **$4,196** for browser execution and proxy bandwidth alone. On Startup, it is **$3,499**. Both estimates exclude Fetch, Extract, Search, and model tokens.
Browserbase charges separately for proxy bandwidth, at $12/GB on Developer and $10/GB on Startup.
Zenrows handles the same workload through success-based billing. Using the **100 percent success rate from our benchmark** as the assumption, all 10,000 daily attempts would succeed and consume credits. Our `mode=auto` test showed that some successful Cloudflare-protected requests used both JavaScript rendering and premium proxies, applying a 25× credit multiplier. If every successful request required both, the workload would consume **7.5 million credits** per month, which will cost **$622** on the Scale plan.
The breakdown below shows the browser hours, proxy usage, and monthly cost for the same 10,000-page daily workload on both platforms.
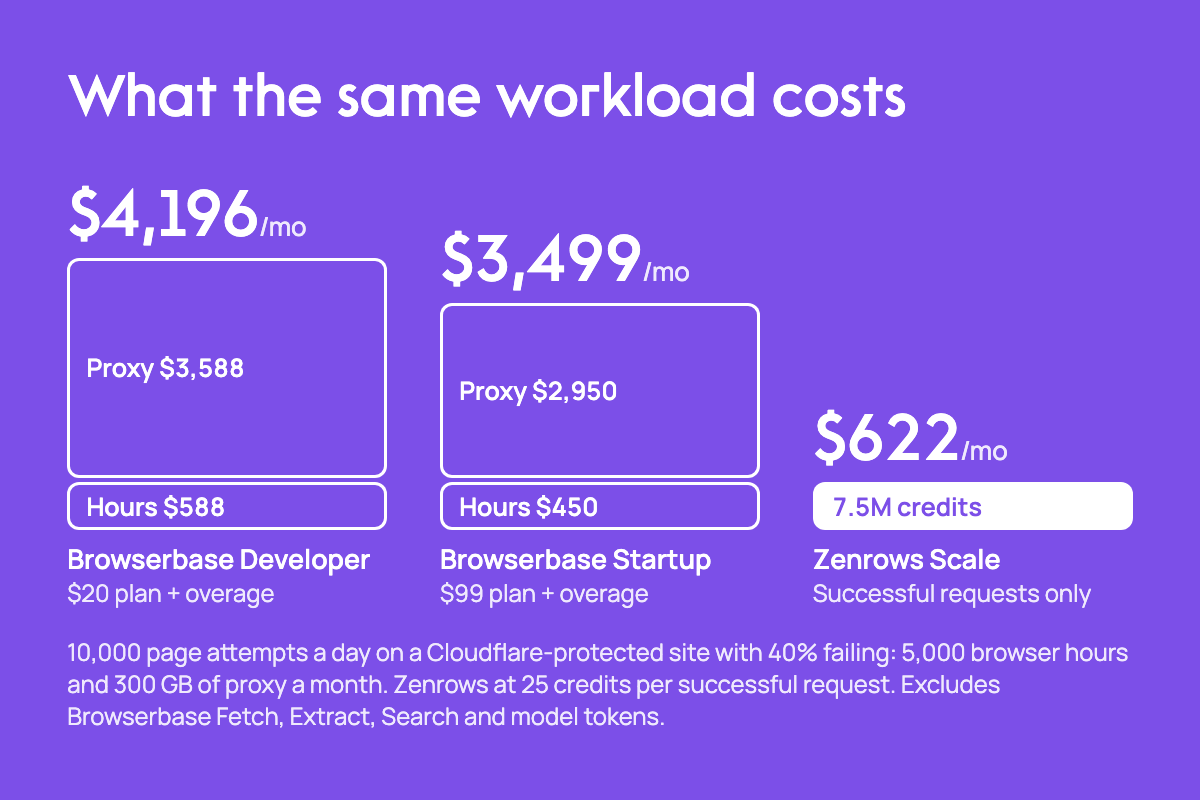
A workload that fits within Browserbase Startup's 500 browser hours when sessions are short and successful quickly exceeds the allocation when failures trigger retries, longer waits, or additional browser usage. Browserbase's pricing page lists the unit costs, but the final bill depends on your session durations and proxy bandwidth usage. For a protected-site extraction, you have to estimate those variables before calculating the monthly cost. Zenrows' calculation starts with the number of successful requests and the configuration required to retrieve them.
## Why Zenrows Is the Best Browserbase Alternative for Data Extraction
**Zenrows is the web data infrastructure layer: protected access, structured output, and job orchestration.** Fetch pricing starts at $16/month on the Build plan and charges only for successful requests. A basic request consumes one credit, JavaScript rendering adds a 5× multiplier, proxies add 10×, and activating both capabilities adds a 25× credit multiplier. These credit weights remain the same on every plan.
Zenrows Fetch uses `mode=auto` to adapt the request configuration to the target's protection level, activating JavaScript rendering, residential proxies, or both when required. This setup reduces the need to manage browser lifecycles or to build recovery logic for individual requests.
Fetch also retrieves content as Markdown, plain text, or structured JSON using [Extract](https://docs.zenrows.com/extract/setup), for LLM (Large Language Model) and RAG (Retrieval-Augmented Generation) pipelines. You can select a format using the `response_type` parameter, without manual HTML parsing around raw browser output.
For bulk extraction, Batch processes up to 100,000 URLs per job and handles queuing, concurrency, retries, result tracking, storage, and completion notifications. Batch removes the application-level orchestration you would otherwise need to build around individual requests.
When a page requires browser interaction, Zenrows [Browser](/products/browser) supports navigation, clicking, form submission, and persistent session state. It works with Playwright, Puppeteer, and other CDP (Chrome DevTools Protocol) compatible tools, so you can replace your local browser initialization with a Zenrows remote WebSocket URL without changing your browser workflow. Browser is available through the API, SDK, CLI, and MCP (Model Context Protocol) server.
The example below uses Playwright to connect to Zenrows Browser, navigate to an IKEA product page, wait for the page content, and extract the title.
```python
# pip install playwright
# playwright install chromium
import os
from playwright.sync_api import sync_playwright
API_KEY = os.environ.get("ZENROWS_API_KEY")
# construct the remote browser websocket endpoint
connection_url = f"wss://browser.zenrows.com?apikey={API_KEY}"
with sync_playwright() as p:
# connect to the zenrows remote browser
browser = p.chromium.connect_over_cdp(connection_url)
page = browser.new_page()
try:
print("navigating to target page through zenrows browser session...")
page.goto(
"https://www.ikea.com/us/en/p/kallax-shelf-unit-white-80275887/",
wait_until="domcontentloaded"
)
# wait for the product content to load
print("waiting for product content to load...")
page.locator("body").wait_for()
# extract information from the live page
title = page.title()
print(f"page title: {title}")
finally:
# close the remote session
browser.close()
```
Output:
```text
navigating to target page through zenrows browser session...
waiting for product content to load...
page title: Products - IKEA
```
### Migrating From Browserbase Fetch to Zenrows
Migrating a basic Fetch request from Browserbase to Zenrows requires only changes to the API endpoint, authentication, HTTP method, and request parameters. The target URL and the way your application handles the returned content remain the same.
Browserbase Fetch uses a POST request to `https://api.browserbase.com/v1/fetch`, with the target URL in the JSON body, as shown below. The default response is raw content. If you need Markdown or schema-constrained JSON, you have to add the separate Fetch Extract feature and configure its format or schema parameters. Fetch Extract costs more than normal Fetch, and Browserbase prices it separately.
```python
# pip install browserbase
import os
from browserbase import Browserbase
bb = Browserbase(api_key=os.environ.get("BROWSERBASE_API_KEY"))
response = bb.fetch_api.create(
url="https://www.ikea.com/us/en/p/kallax-shelf-unit-white-80275887/"
)
print(f"status code: {response.status_code}")
print(f"content type: {response.content_type}")
print(f"page content:\n{response.content[:2000]}")
```
Output:
```text
# output truncated for brevity
status code: 200
content type: text/html; charset=UTF-8
page content:
```
Zenrows uses a GET request to `https://api.zenrows.com/v1/`. The request includes the API key, target URL, and Fetch configuration as query parameters.
```python
# pip install requests
import os
import requests
API_KEY = os.environ.get("ZENROWS_API_KEY")
TARGET_URL = "https://www.ikea.com/us/en/p/kallax-shelf-unit-white-80275887/"
params = {
"url": TARGET_URL,
"apikey": API_KEY,
"mode": "auto",
}
response = requests.get(
"https://api.zenrows.com/v1/",
params=params
)
print(f"status code: {response.status_code}")
print(f"page content:\n{response.text[:2000]}")
```
Output:
```text
# output truncated for brevity
status code: 200
page content:
```
The migration is straightforward for basic retrieval. Zenrows keeps protected retrieval and structured output within the Fetch workflow, while Browserbase separates those capabilities across Fetch and Extract.
## Anti-Bot Performance: Zenrows vs. Browserbase Tested
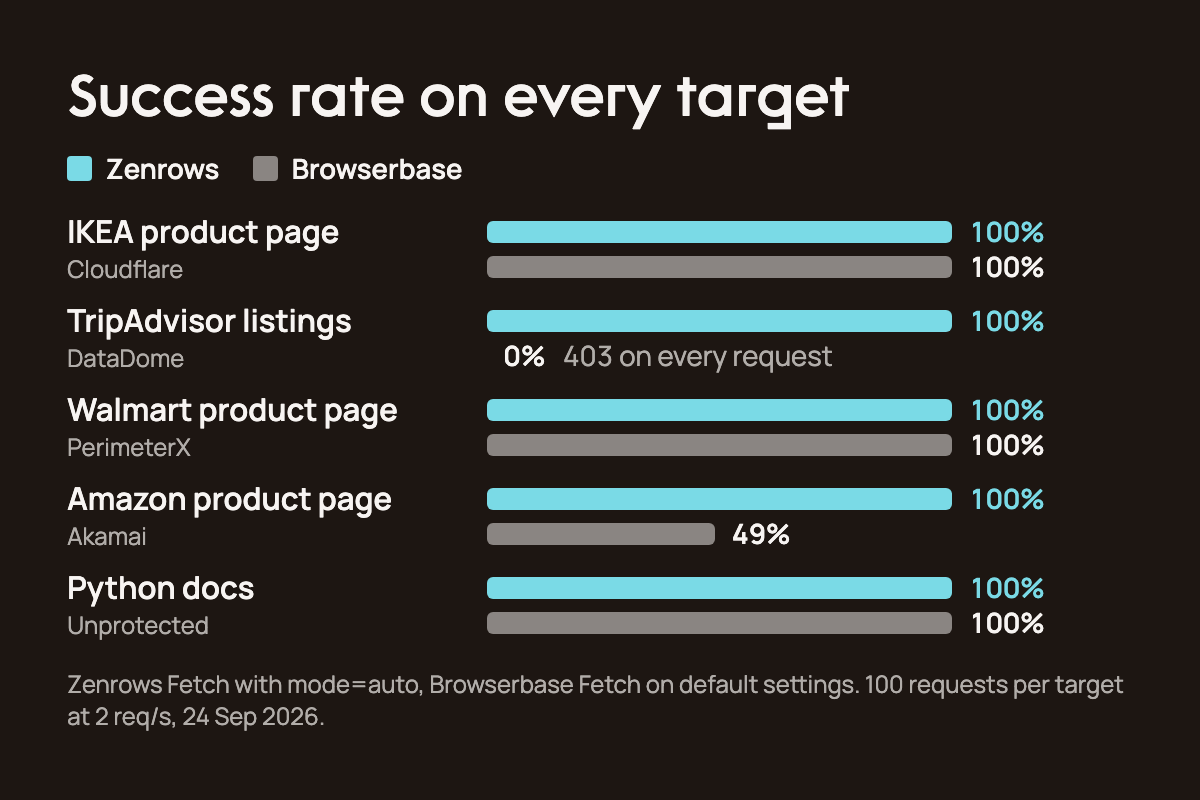
**Zenrows performed better than Browserbase Fetch on the protected-site tests, achieving a 100 percent success rate across the four protected targets compared with 62.25 percent for Browserbase.**
We tested Zenrows Fetch and Browserbase Fetch **on September 24, 2026, with 100 requests per target at 2 req/s across four protected targets and one unprotected page**. The test used each platform's default configuration for the comparison. Zenrows ran with `mode=auto`, while Browserbase ran with its default Fetch configuration, where the [proxy network is disabled by default](https://docs.browserbase.com/platform/fetch/overview#python). We kept those defaults to evaluate each platform's standard Fetch workflow without browser sessions or additional configuration. We did not test Zenrows Browser and Browserbase Sessions API, Extract, or Search.
The five targets represented different protection systems:
- [IKEA product page](https://www.ikea.com/us/en/p/kallax-shelf-unit-white-80275887/) (Cloudflare)
- [TripAdvisor restaurant listings](https://www.tripadvisor.com/Restaurants-g187147-Paris_Ile_de_France.html) (DataDome)
- [Walmart product page](https://www.walmart.com/ip/AirPods-Pro-2nd-generation-with-MagSafe-Case-USB-C/5689919121) (PerimeterX)
- [Amazon product page](https://www.amazon.com/dp/B09W2H338D) (Akamai)
- [Python 3.14.7 documentation page](https://docs.python.org/3/) (unprotected)
For each request, we checked the HTTP 200 status code, page title, and response time. The benchmark script and CSV results are available on [GitHub](https://github.com/ZenRows/zenrows-vs-browserbase-benchmark).
### Zenrows Test Results
Zenrows Fetch delivered the strongest result in this benchmark because `mode=auto` escalated only when a target needed more than the default request path. It had a 100% success rate on the four protected sites.
### Browserbase Test Results
Browserbase Fetch achieved a **62.25 percent success rate** across the four protected targets, and 100 percent on the unprotected Python documentation page. It returned 100 percent of requests from IKEA and Walmart, 49 percent from the Amazon product page, and failed all 100 TripAdvisor requests, returning a 403 status code and no page title.
The result is consistent with the default Fetch configuration we tested. Browserbase Fetch does not execute JavaScript, and its proxy network is disabled by default. Reaching TripAdvisor, which uses DataDome, requires [browser fingerprinting](/blog/browser-fingerprinting) through the Sessions API. That introduces another layer of browser session management to a data extraction task.
Browserbase also recorded a 42 percent success rate on the [Browser Use Stealth Benchmark](https://browser-use.com/posts/stealth-benchmark), which tested its cloud browsers across 71 protected websites and interactive browser tasks. That benchmark tested Browserbase's browser infrastructure rather than the Fetch API used in our test, so the two results measure different configurations and workflows. Our benchmark used 500 Fetch calls, which were covered by the allocated Fetch calls in Browserbase's $20/month Developer plan.
The chart and the table below show the success rate and average response time for each target.
| Target | Zenrows average response time (s) | Browserbase average response time (s) |
| --- | --: | --: |
| **IKEA product page** | 1.81 | 1.75 |
| **TripAdvisor Paris restaurant listings** | 5.63 | 0.61 |
| **Walmart AirPods product page** | 4.52 | 1.68 |
| **Amazon product page** | 14.23 | 1.36 |
| **Python 3.14.7 documentation** | 0.61 | 0.52 |
Zenrows averaged 5.36s across the five targets, compared with 1.18s for Browserbase. However, consider the response time alongside the retrieval success. For example, Browserbase averaged 0.61s on TripAdvisor but returned a 403 response for all 100 requests, while Zenrows successfully retrieved the target. **A faster response does not mean faster access to the requested content.**
## When Browserbase Is Still the Right Choice
Choose Browserbase when your AI agent needs to operate a browser rather than retrieve page content. Its managed browser infrastructure gives AI agents and automation workflows direct control over pages, sessions, and browser state without requiring you to maintain the underlying headless browser fleet.
Browserbase remains the fit when you need to do any of the following.
### 1. You Are Building an AI Agent That Operates Inside Websites
Browserbase gives an agent a headless browser it can control through CDP or Playwright, allowing it to navigate pages, authenticate, fill forms, and automate multi-step workflows. Its Stagehand layer also supports natural-language browser actions through parameters such as `act`, `observe`, and `extract`.
### 2. You Need Session Replay and Visual Debugging
Browserbase records sessions and provides tools for replaying the video and embedding it inside your own product. The Live View feature provides real-time DOM (Document Object Model) inspection and session control for active sessions, while Session Inspector exposes the network activity, console output, and session timelines. For complex agent workflows and failures that are hard to reproduce, this visibility helps you catch login issues, unexpected interface changes, or failed interactions.
### 3. Your Existing Automation Depends on Playwright and Custom Proxies
Browserbase is a good fit if you already have active Playwright automation and want to keep using your existing proxy stack. It lets you move the browser runtime to managed infrastructure without rewriting the workflow or changing proxy handling. Browserbase also supports external HTTP and HTTPS proxies with credentials, and domain-based routing.
### 4. Your Workflow Depends on Chrome Extensions or Persistent Browser State
For applications that must remain authenticated or reuse browser storage across requests, Browserbase supports Chrome extensions and persists browser data, including cookies, authentication tokens, and local storage. You can upload your extension via the SDK and create a session with the extension enabled. Zenrows Browser provides remote Chrome instances, but it does not currently support custom Chrome extensions.
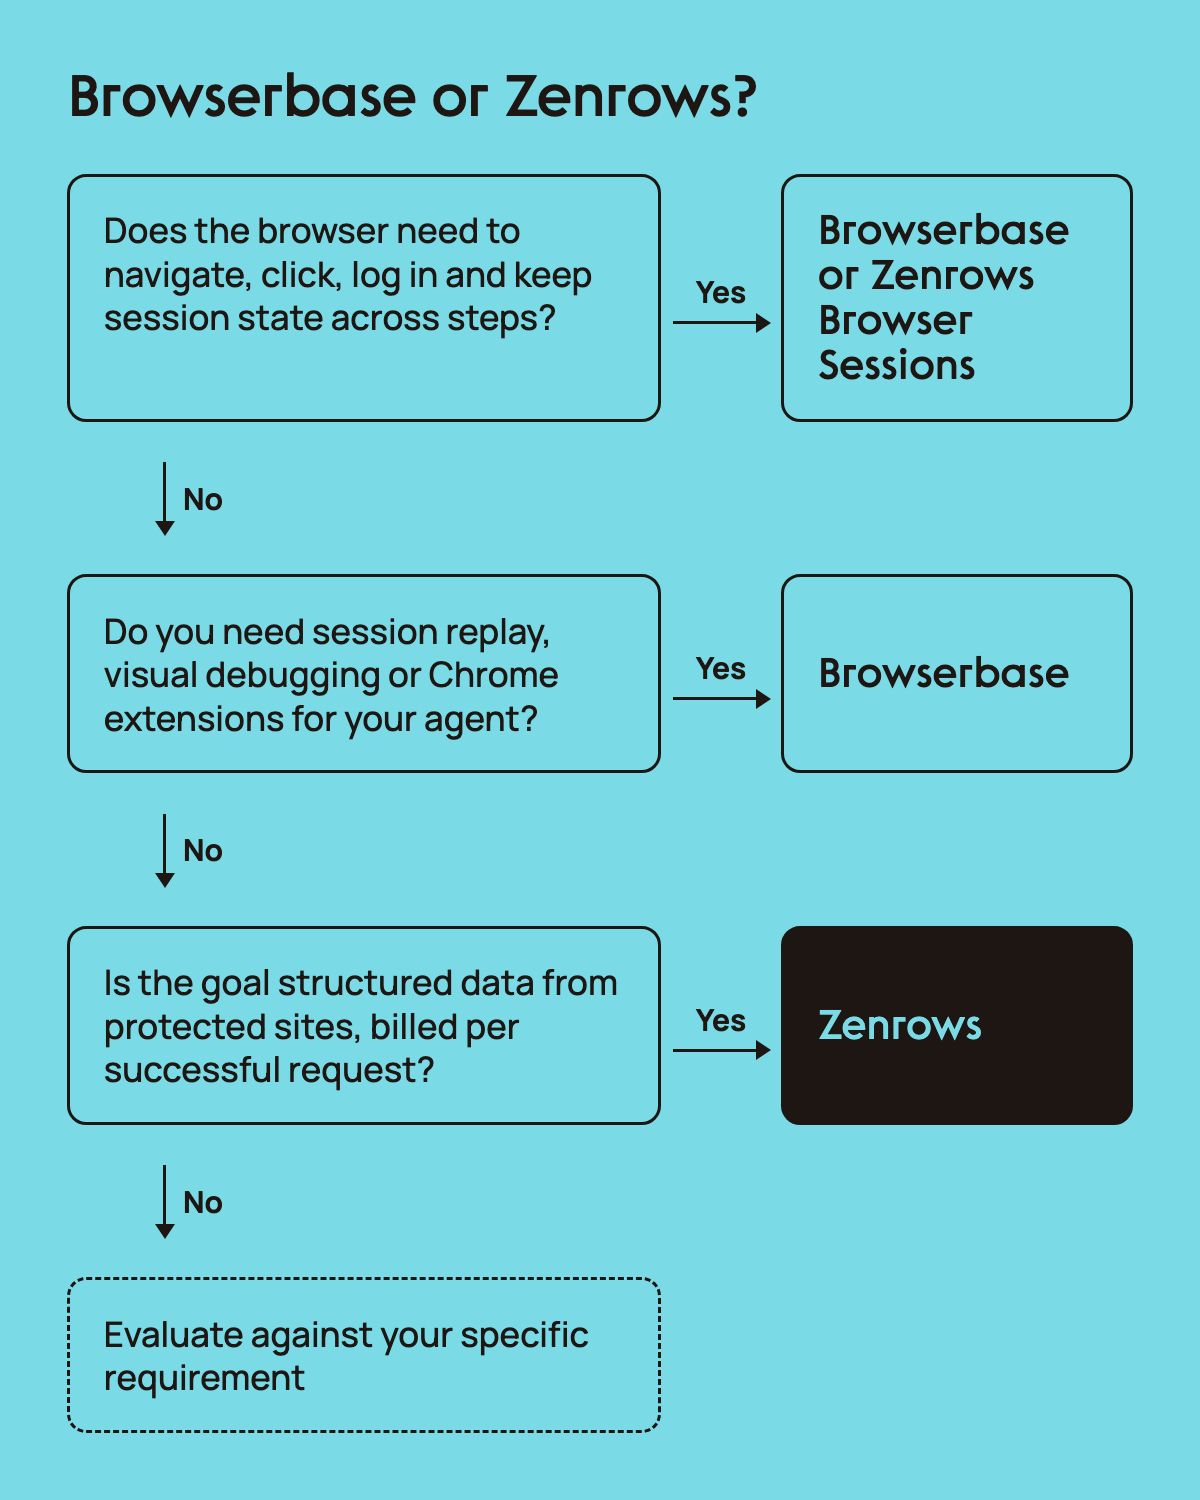
The flowchart below shows when to choose Browserbase, Zenrows, or evaluate another tool.
## Other Browserbase Alternatives Worth Knowing
The right Browserbase alternative depends on whether you need browser control, managed web access, structured extraction, or infrastructure you can run yourself. Playwright and Browserless give you more control over the browser layer, while Bright Data and Oxylabs combine web access with proxy and anti-bot infrastructure. Firecrawl and ScrapingBee are the closest to API-first extraction tools.
### Playwright (Self-Hosted)
Playwright is a strong open-source Browserbase alternative for teams that want maximum control over their browser infrastructure for local development and testing. It supports Chromium, Firefox, and WebKit, and it gives developers control over browser context, network configuration, and automation. The tradeoff is that your team owns the browser runtime and handles the protected-site access, proxy management, and scaling.
### Bright Data Scraping Browser
Bright Data's Scraping Browser (now Browser API) runs Puppeteer, Playwright, or Selenium workloads on managed Chromium browsers and includes proxy management, JavaScript rendering, and CAPTCHA solving. However, [Bright Data](/blog/best-bright-data-alternative-for-self-service-scraping) charges for proxy bandwidth rather than successful extraction, so the cost follows the amount of browser traffic your workflow generates. The current pay-as-you-go price is $8/GB.
### Oxylabs
Oxylabs is positioned toward enterprise web data collection, with a 175M+ proxy network and products for web scraping and AI-powered extraction. Its AI Studio includes AI Scraper for page-level extraction, AI Crawler for multi-page collection, and Browser Agent for workflows that require browser interaction. Oxylabs Web Scraper API starts at $49/month, while residential proxies start at $6/GB on its self-service offering. It is the right fit when you need proxy scale, geographic coverage, or high-volume data retrieval for market intelligence.
### Firecrawl
[Firecrawl](/blog/best-firecrawl-alternative-for-anti-bot-bypass) is an API-first web data platform for AI applications. Its API returns clean Markdown, structured JSON, HTML, and screenshots. Use Firecrawl if you're extracting LLM-ready data from documentation sites, product pages, and search results, or crawling site-wide content for AI training and Retrieval-Augmented Generation (RAG). However, its performance on protected sites is less consistent. [Proxyway's benchmark](https://proxyway.com/research/web-scraping-api-report-2025) recorded a 33.69 percent average success rate across 15 protected targets at 2 req/s.
### Browserless
Browserless is a good fit for teams that already work with Docker and want to run browser automation in a containerized environment. Its open-source Docker image runs headless Chrome with Puppeteer, Playwright, and REST APIs on your own infrastructure, while its hosted platform adds managed browser execution and BrowserQL, a GraphQL-based automation API that improves browser fingerprinting and CAPTCHA solving. Browserless also has a Live Debugger for inspecting browser scripts and session behavior. The self-hosted deployment gives you infrastructure control, but you own the scaling, orchestration, and proxy configuration.
### ScrapingBee
ScrapingBee offers a scraping API that manages JavaScript rendering and proxy rotation. It's best suited for teams that want web data access on minimally protected sites without persistent browser control or interaction. Its current Freelance plan starts at $49, with 250,000 API credits and 50 concurrent requests. But protected sites can quickly consume API credits.
The table below shows the key differences between these six Browserbase alternatives. We included our test results for Zenrows and Browserbase, and labeled Proxyway and Browser Use Stealth benchmarks separately.
| Feature | Zenrows | Browserbase | Playwright | Bright Data Scraping Browser | Oxylabs | Firecrawl | Browserless | ScrapingBee |
| --- | --- | --- | --- | --- | --- | --- | --- | --- |
| **Anti-bot success rate on protected sites** | 100% (our test) | 62.25% (our test) | Not tested | Not tested | 85.82% on Proxyway | 33.69% on Proxyway | 54% on Browser Use Stealth benchmark | 84.47% on Proxyway benchmark |
| **Billing model on failed requests** | Only successful requests consume credits | Bills browser and proxy usage regardless of extraction success | No platform billing, you pay for your own infrastructure | Billed by GB of traffic, regardless of request outcome | System failures (5xx/6xx) are not billed, 2xx/4xx results are billable | Credit usage depends on the operation, scraping credits are consumed based on the selected configuration | Browser time, proxy traffic, and CAPTCHA attempts consume units, usage continues while the session remains open | Failed requests are not charged |
| **Entry price** | $16/month | $20/month | Self-hosted, infrastructure cost only | $8/GB pay-as-you-go | $49/month for Web Scraper API | $19/month | Free hosted tier, $25/month when billed annually | $49/month |
| **Residential proxy cost** | Included through 10× credit multiplier | $12/GB overage | Bring your own | $8/GB for Scraping Browser | $6/GB | Managed within platform pricing | Included in hosted monthly plan | Included through API credits |
| **Structured output included** | Yes, Markdown, plain text, JSON via Extract | Fetch returns raw content, Extract adds structured output | No built-in extraction output | No, only raw HTML or screenshots | Yes, AI Studio and Web Scraper API support structured output | Yes, Markdown and schema-based JSON | Yes, structured JSON through BrowserQL | Yes, structured JSON or Markdown from CSS or XPath extraction rules |
| **Self-service signup** | Yes | Yes | Yes | Yes | Yes | Yes | Yes | Yes |
| **Free plan** | 5,000 credits, 5 concurrent requests | 3 concurrent, 1 browser-hour, 15-min sessions | Free | 7 days free trial | 7 days free trial | 1,000 pages, 2 concurrent requests | 1,000 compute units | 1,000 credits |
| **Session replay/debugging** | No | Yes | Yes, Trace Viewer | Yes, real-time browser monitoring | No | No | Yes | No |
| **Bring-your-own-proxy support** | No | Yes | Yes | No | No | No | Yes, for self-hosted deployments | No |
## Choose Zenrows for Protected Web Data Extraction
Zenrows is the best Browserbase alternative for developers who need reliable access to protected web data without building the workflow around a browser. Fetch handles the retrieval and protection layer, Extract retrieves structured JSON responses, and Batch coordinates high-volume extraction jobs. Our benchmark showed a 100 percent success rate for Zenrows across the protected targets we tested, with a success-based pricing model.
[Sign up for Zenrows](https://app.zenrows.com/register) and start testing your own targets.
## FAQs
### What Is Browserbase Used For?
Browserbase provides managed cloud browsers for AI agents and browser automation. Agents can navigate websites, click elements, fill forms, and maintain browser state without your team managing the browser infrastructure.
### Why Did Browserbase Fetch Fail on DataDome-Protected Pages?
Browserbase Fetch does not execute JavaScript and disables proxies by default. In our test, this configuration returned zero successful responses from the DataDome-protected TripAdvisor target. Browserbase documentation explicitly states that pages that require JavaScript rendering should use a browser session.
### Is There a Free Alternative to Browserbase?
Yes, Playwright is free and open source and can run Chromium, Firefox, or WebKit locally. You manage the browser runtime, scaling, proxy infrastructure, and protected page access.
### Does Zenrows Replace Browserbase for AI Agent Workflows?
Yes, Zenrows replaces Browserbase when an agent needs to retrieve and process web content through an API. Browserbase fits agents that need direct browser control, persistent browser state, visual debugging, or interactive multi-step workflows.
### What Is Cheaper Than Browserbase for Data Extraction?
Zenrows costs less for workloads where the main requirement is successful data retrieval. Its Fetch API charges based on the configuration that successfully retrieves the page, while Browserbase charges separately for browser and proxy usage.
### How Long Does Switching From Browserbase to Zenrows Take?
You can migrate a basic Browserbase Fetch request to Zenrows Fetch by changing the endpoint, authentication, HTTP method, and request parameters. Browser automation workflows require a different migration path because they use browser sessions rather than Fetch.
### Does Browserbase Charge for Failed Sessions?
Browserbase charges for active browser time, so a session can consume billable browser hours even when the automation does not successfully retrieve the intended data.
### What Is the Difference Between Browserbase's Fetch API and Zenrows Fetch?
Browserbase Fetch retrieves the raw HTTP response without executing JavaScript, while Zenrows Fetch uses `mode=auto` to select the request configuration needed to retrieve the target page. Browserbase Fetch supports proxies as an optional setting and currently returns Markdown and structured JSON output through a separate Extract feature. Zenrows retrieves structured output directly and can escalate to JavaScript rendering and premium proxies when required.