---
title: "How to Scrape Indeed Job Listings with Python (Jobs, Salaries & Company Data)"
description: "A working Indeed scraper in Python that collects search results, full job descriptions and structured salaries, then turns hiring activity into a lead list. Every script was run against Indeed in October 2026."
---
# How to Scrape Indeed Job Listings with Python (Jobs, Salaries & Company Data)
> A working Indeed scraper in Python that collects search results, full job descriptions and structured salaries, then turns hiring activity into a lead list. Every script was run against Indeed in October 2026.
Source: https://www.zenrows.com/blog/indeed-scraper
Indeed is the world's top job site by total visits, and it runs in more than 60 countries with over 3.5 million employers hiring on it, according to [Indeed's own figures](https://www.indeed.com/about). That makes it one of the most comprehensive public datasets for understanding company hiring. That data supports salary benchmarking, skills-demand analysis, hiring-trend analysis, talent mapping, and competitor-hiring monitoring.
Beyond labor market analytics, job postings also support go-to-market (GTM) intelligence, as hiring activity signals budget allocation, team growth, and software needs. For example, a company hiring ten Salesforce admins is a prospect for customer relationship management (CRM) tooling. In this tutorial, you'll learn how to scrape Indeed job listings with Python. You'll scrape job search results, open job detail pages, extract salary data, and export job and company data without being blocked.
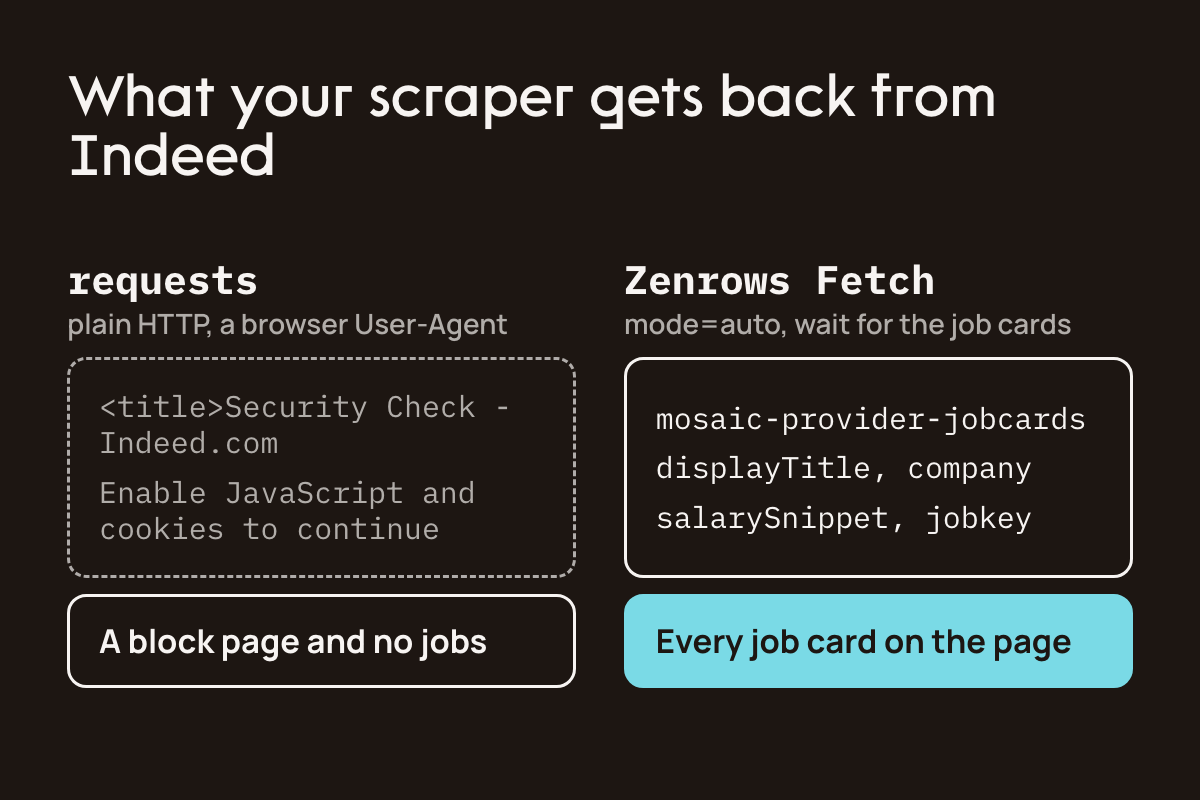
**The short version: Indeed keeps its job data in a JavaScript object inside the search page, and plain Python requests get a Cloudflare security check instead of that page. Fetch the page through [Zenrows](/products/fetch) with `mode=auto`, wait for the job cards to render, and parse the embedded JSON.** Every script below ran against Indeed on October 16, 2026, and the outputs are copied from those runs. The complete code is in the [indeed-scraper-zenrows repository on GitHub](https://github.com/ZenRows/indeed-scraper-zenrows).
## What Data Can You Scrape From Indeed?
Indeed spreads job and company data across search results, job detail pages, and company profiles.
- **Search results pages**: At the listing level, Indeed shows the job title, company name, location, salary range (where shown), posting date, job type (full-time/remote/contract), snippet text, and job URL.
- **Individual job detail pages**: For each role, Indeed provides the full job description, required skills/qualifications, benefits, exact salary (where disclosed), application deadline, company size, company rating, and number of applicants.
- **Company pages**: On company profiles, Indeed includes the company overview, headquarters, size, industry, overall rating, review count, and interview difficulty score.
To access all three page types at scale, you'll need to handle Indeed's anti-bot protections first.
## Does Indeed Have an API for Job Listings?
No public one. Indeed has retired its Publisher Job Search API, the API developers once used to read job listings, and it no longer issues keys for it. Indeed's current developer APIs serve employers and applicant tracking system (ATS) partners: they post jobs and manage applications, and they need Indeed's approval. If you want to read job listings programmatically, you collect them from Indeed's public pages, which is what the rest of this guide does.
## How Indeed Blocks Scrapers and Why Custom Approaches Fail
Indeed blocks automated traffic using several measures. Here are the main ones.
- [**Cloudflare with JS challenge pages**](/blog/bypass-cloudflare-python): Before returning job data, Indeed uses Cloudflare to evaluate incoming traffic. When Cloudflare classifies a request as automated, it serves a [JavaScript challenge](/glossary/web-data-access/what-is-a-javascript-challenge) page instead of the search results HTML.
- **Embedded JavaScript variables**: Key job data appears inside JavaScript state objects in the HTML, not only in regular HTML elements. That's why [BeautifulSoup](https://docs.zenrows.com/fetch/help/python-requests-and-beautifulsoup-integration) alone can miss fields such as job metadata, salary details, and pagination data.
- **Client-side rendering**: Indeed now builds its search page in the browser. The first HTML response is a loading shell, and the job cards only appear after the page's JavaScript runs, so a scraper has to [render JavaScript](/glossary/web-data-access/what-is-javascript-rendering) and wait for the cards.
- **Rate limiting**: Indeed applies aggressive per-IP request throttling, especially on search endpoints. Scraping many keywords, locations, job pages, or paginated URLs from the same IP address can trigger [rate limits](/blog/web-scraping-rate-limit).
- **Bot behavior detection**: The site checks request patterns, [browser fingerprints](/glossary/web-data-access/what-is-browser-fingerprinting), and [TLS fingerprints](/glossary/web-data-access/what-is-tls-fingerprinting) to separate normal user traffic from automated traffic. A scraper based only on `requests` gets blocked because it sends an HTTP request without the full browser network profile, session state, and navigation behavior. [How websites detect scrapers](/glossary/web-data-access/how-do-websites-detect-scrapers) covers these signals in more depth.
Let's see how Indeed responds when you use plain `requests`:
```python
import requests
url = "https://www.indeed.com/jobs?q=python+developer&l=New+York%2C+NY"
headers = {
"User-Agent": (
"Mozilla/5.0 (Windows NT 10.0; Win64; x64) "
"AppleWebKit/537.36 (KHTML, like Gecko) "
"Chrome/147.0.0.0 Safari/537.36"
),
"Accept": (
"text/html,application/xhtml+xml,application/xml;q=0.9,"
"image/avif,image/webp,image/apng,*/*;q=0.8"
),
}
response = requests.get(url, headers=headers)
print(response.status_code)
print(response.text[:500])
```
When you run the code, the output is as follows:
```
403
Security Check - Indeed.com
Additional Verification Required
Please enable JavaScript to complete the security check.
```
The [request failed with a 403 status code](/blog/403-web-scraping), returning Indeed's Cloudflare security check page instead of job data.
## Scraping Indeed Job Search Results
Before you can scrape individual job pages, you need to find the listings that match your target keyword and location. That starts with an Indeed search results page. Let's see how to scrape that page with Python and Zenrows.
### Step 1: Prerequisites
Before you start coding, make sure you have the following.
- [Python 3](https://www.python.org/downloads/) installed on your computer.
- The requests package installed on your development environment.
```bash
pip3 install requests
```
- A Zenrows API key. [Sign up](https://app.zenrows.com/register?prod=universal_scraper) for the free plan, which includes 5,000 credits every month with no credit card required. Then open the [Playground](https://app.zenrows.com/fetch) and copy your API key.
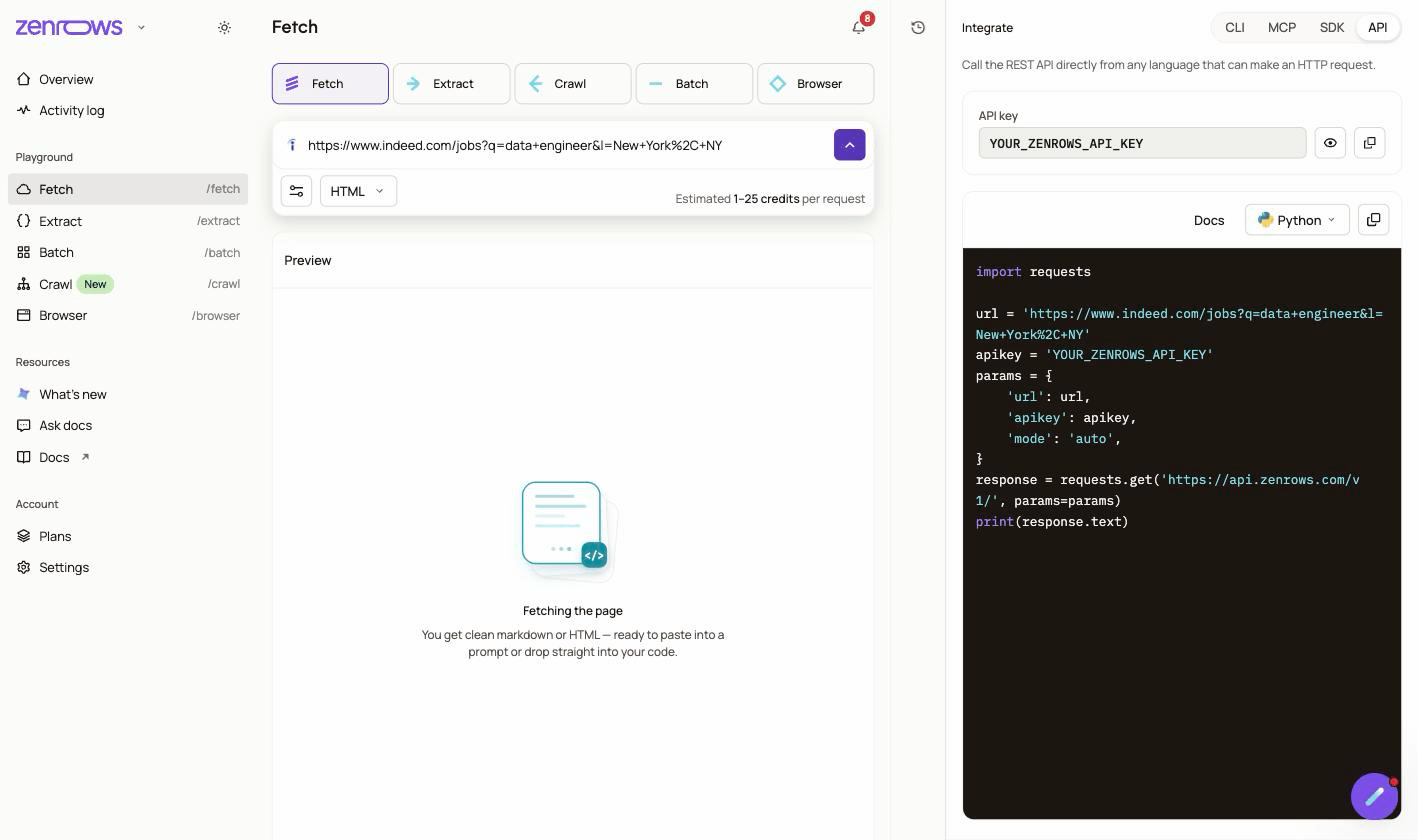
For Indeed, you'll require `mode=auto` in the Zenrows request. This activates [Adaptive Stealth Mode](https://docs.zenrows.com/fetch/features/adaptive-stealth-mode), which automatically applies JavaScript Rendering for JS challenge pages and Premium Proxies to eliminate blocks tied to IP reputation and [per-IP throttling](/blog/how-to-bypass-ip-ban), based on what Indeed's request needs.
Because Indeed renders its job cards in the browser, the request also carries a [`wait_for` JavaScript instruction](https://docs.zenrows.com/fetch/features/js-instructions) for the `[data-jk]` selector, the attribute every job card has. Zenrows then returns the HTML once the cards are on the page, not the loading shell. This is one of the [wait strategies](/glossary/web-data-access/what-are-wait-strategies) that dynamic sites need.
### Step 2: Understand Indeed's Search URL Structure
Indeed search URLs show how a search is built. The base path points to the jobs search page, and the [query parameters](/glossary/web-crawling/what-are-url-parameters) define the keyword, location, posting date, salary filter, and job type.
For instance, searching for Python developer jobs in New York, NY, on Indeed, filtered to full-time roles posted in the last seven days, gives you this URL.
```
https://www.indeed.com/jobs?q=python+developer&l=New+York%2C+NY&fromage=7&jt=fulltime
```
The key parameters are:
| Parameter | What it does | Example |
| --- | --- | --- |
| `q` | Sets the search term | `q=python+developer` targets Python developer listings |
| `l` | Defines the search area | `l=New+York%2C+NY` points the search to New York, NY |
| `fromage` | Limits results by posting age, in days | `fromage=7` returns listings posted in the last seven days |
| `sc` | Applies a salary filter | Indeed adds this parameter when you choose a salary range in the browser |
| `jt` | Filters by job type | `jt=fulltime`; other options include `parttime`, `contract`, and `internship` |
| `filter` | Turns Indeed's duplicate filtering on or off | `filter=0` returns the full result set |
| `vjk` | Opens one job in the side panel | `vjk=` adds that job's full details to the page |
These parameters let you build Indeed search URLs directly in Python for the roles, locations, and filters you want to scrape.
### Step 3: Parse Embedded JavaScript Job Data
Indeed search pages don't expose all listing data as normal HTML elements. The search result data appears inside the `window.mosaic.providerData["mosaic-provider-jobcards"]` JavaScript variable. That object contains the job cards model, including the listings returned for the keyword and location.
Let's extract that data from a search for data engineer jobs in New York.
```
https://www.indeed.com/jobs?q=data+engineer&l=New+York%2C+NY&filter=0
```
Start by creating a `scraper.py` file and importing the required libraries. You'll use them to request the page through Zenrows, format the Indeed search URL, extract the embedded JavaScript object, and parse it as JSON.
```python
# pip3 install requests
import re
import json
import requests
from urllib.parse import urlencode
```
Next, configure your Zenrows API key and define a function that sends each scrape request to Zenrows and receives the target URL's rendered HTML.
```python
# ...
# replace with your Zenrows API key from app.zenrows.com
APIKEY = ""
def fetch_page(url):
# mode="auto" activates Adaptive Stealth Mode
# wait_for holds the response until Indeed has rendered the job cards
params = {
"url": url,
"apikey": APIKEY,
"mode": "auto",
"js_instructions": json.dumps([{"wait_for": "[data-jk]"}]),
}
response = requests.get("https://api.zenrows.com/v1/", params=params)
response.raise_for_status()
return response.text
```
Now define the parser. This function finds the `mosaic-provider-jobcards` JavaScript object and converts it into a Python dictionary. A second helper reads the job type, which Indeed now stores in each card's taxonomy attributes.
```python
# ...
def parse_search_page(html):
# Indeed stores job data in a JS variable rather than plain HTML elements.
# use regex to extract the JSON block and parse it into a Python dict.
data = re.findall(
r'window\.mosaic\.providerData\["mosaic-provider-jobcards"\]=(\{.+?\});',
html
)
if not data:
return {"results": [], "meta": []}
data = json.loads(data[0])
return {
"results": data["metaData"]["mosaicProviderJobCardsModel"]["results"],
"meta": data["metaData"]["mosaicProviderJobCardsModel"]["tierSummaries"],
}
def get_job_types(job):
# job types live in the taxonomy attributes, under the "job-types" group
for group in job.get("taxonomyAttributes", []):
if group.get("label") == "job-types":
return [attribute["label"] for attribute in group.get("attributes", [])]
return []
```
The regex targets the JavaScript assignment that stores the search results. If the object isn't found, the function returns empty `results` and `meta` values instead of raising an error. When the object is found, `json.loads()` parses it, and the function returns the results array that contains the job listings.
Build the Indeed search URL for the target keyword and location.
```python
# ...
# q = keyword, l = location, filter = 0 disables Indeed's deduplication
search_url = "https://www.indeed.com/jobs?" + urlencode({
"q": "data engineer",
"l": "New York, NY",
"filter": 0,
})
```
The search URL targets data engineer jobs in New York. It also includes `filter=0`, which disables Indeed's duplicate filtering. Without it, Indeed collapses duplicate or very similar job listings into a single result, which reduces the number of jobs returned.
Finally, request the search page, parse the embedded data, and print one dictionary per listing.
```python
# ...
html = fetch_page(search_url)
page_data = parse_search_page(html)
for job in page_data["results"]:
print({
"title": job.get("displayTitle"),
"company": job.get("company"),
"location": job.get("formattedLocation"),
# not every listing shows a salary, so .get() returns None when it's missing
"salary": (job.get("salarySnippet") or {}).get("text"),
"salary_source": (job.get("salarySnippet") or {}).get("source"),
"job_type": get_job_types(job),
"remote": job.get("remoteLocation"),
"posted": job.get("formattedRelativeTime"),
"company_rating": job.get("companyRating"),
"review_count": job.get("companyReviewCount"),
# jobkey is the unique job ID used to fetch the full detail page
"jobkey": job.get("jobkey"),
})
```
Each dictionary contains the fields returned in the search result data, including the title, company, location, salary text, salary source, job type, remote flag, posting date, company rating, review count, and jobkey.
Here is the full code:
```python
# pip3 install requests
import re
import json
import requests
from urllib.parse import urlencode
# replace with your Zenrows API key from app.zenrows.com
APIKEY = ""
def fetch_page(url):
# mode="auto" activates Adaptive Stealth Mode
# wait_for holds the response until Indeed has rendered the job cards
params = {
"url": url,
"apikey": APIKEY,
"mode": "auto",
"js_instructions": json.dumps([{"wait_for": "[data-jk]"}]),
}
response = requests.get("https://api.zenrows.com/v1/", params=params)
response.raise_for_status()
return response.text
def parse_search_page(html):
# Indeed stores job data in a JS variable rather than plain HTML elements.
# use regex to extract the JSON block and parse it into a Python dict.
data = re.findall(
r'window\.mosaic\.providerData\["mosaic-provider-jobcards"\]=(\{.+?\});',
html
)
if not data:
return {"results": [], "meta": []}
data = json.loads(data[0])
return {
"results": data["metaData"]["mosaicProviderJobCardsModel"]["results"],
"meta": data["metaData"]["mosaicProviderJobCardsModel"]["tierSummaries"],
}
def get_job_types(job):
# job types live in the taxonomy attributes, under the "job-types" group
for group in job.get("taxonomyAttributes", []):
if group.get("label") == "job-types":
return [attribute["label"] for attribute in group.get("attributes", [])]
return []
# q = keyword, l = location, filter = 0 disables Indeed's deduplication
search_url = "https://www.indeed.com/jobs?" + urlencode({
"q": "data engineer",
"l": "New York, NY",
"filter": 0,
})
html = fetch_page(search_url)
page_data = parse_search_page(html)
for job in page_data["results"]:
print({
"title": job.get("displayTitle"),
"company": job.get("company"),
"location": job.get("formattedLocation"),
# not every listing shows a salary, so .get() returns None when it's missing
"salary": (job.get("salarySnippet") or {}).get("text"),
"salary_source": (job.get("salarySnippet") or {}).get("source"),
"job_type": get_job_types(job),
"remote": job.get("remoteLocation"),
"posted": job.get("formattedRelativeTime"),
"company_rating": job.get("companyRating"),
"review_count": job.get("companyReviewCount"),
# jobkey is the unique job ID used to fetch the full detail page
"jobkey": job.get("jobkey"),
})
```
When you run the code, the output should look like this.
```
{
"title": "Data Engineer",
"company": "BDG",
"location": "New York, NY",
"salary": "$105,000 - $145,000 a year",
"salary_source": "EXTRACTION",
"job_type": ["Full-time"],
"remote": False,
"posted": "30+ days ago",
"company_rating": 3.8,
"review_count": 16,
"jobkey": "018b1c3eb568518f"
}
```
Each printed dictionary represents one Indeed search result. **The run returned 41 listings for one search, because `filter=0` gives you the full result set.** The `jobkey` value is the unique job ID, which you'll use later to fetch the full job details.
These are the job card fields the scraper reads, and what each one holds:
| Field | What it holds |
| --- | --- |
| `jobkey` | The listing's unique ID, used for detail pages and deduplication |
| `displayTitle` | The job title as Indeed shows it |
| `company` | The hiring company's name |
| `formattedLocation` | City and state, or "Remote" |
| `salarySnippet` | The displayed salary text, its currency, and its source |
| `extractedSalary` | Numeric `min`, `max`, and pay period `type`, when Indeed has them |
| `taxonomyAttributes` | Job type, shifts, and remote or hybrid labels |
| `remoteLocation` | `True` when the role is listed as remote |
| `formattedRelativeTime` | The posting age, such as "Just posted" or "3 days ago" |
| `companyRating` and `companyReviewCount` | The company's Indeed rating and number of reviews |
## Scraping Individual Job Detail Pages
Search results display summary fields, but the full job description is available on the job detail page. To reach that page, use the `jobkey` returned by the search results parser. That value identifies the listing and lets you build the detail page URL for each job.
Indeed now opens a job's details in a side panel next to the search results. Add `vjk=` to the search URL, and the page carries that job's full details in an `_initialData` JavaScript object.
In this section, you'll build on the search results scraper. You'll fetch each job detail page, extract the full description and company review data, then save the enriched records to a CSV file.
First, add the extra imports for CSV output and HTML parsing so your full import block looks like this.
```python
# pip3 install requests
import re
import json
import requests
from urllib.parse import urlencode
# added imports
import csv
from html.parser import HTMLParser
```
After the `get_job_types` function, define a helper function to clean each job description. Indeed returns descriptions as HTML, so this function strips the tags before the scraper saves the text to the CSV file.
```python
# ...
# previous search scraper code remains the same
def strip_html(raw):
# removes HTML tags from the job description and returns plain text.
# HTMLParser is part of Python's standard library, no extra install needed.
parser = HTMLParser()
parser.text = []
parser.handle_data = lambda data: parser.text.append(data)
parser.feed(raw)
return " ".join(" ".join(parser.text).split())
```
Next, create the job detail parser. Extract the `_initialData` object, parse it as JSON, and read the full job description, rating, and review count from the panel's response.
```python
# ...
def parse_job_page(html):
# the open job's details sit in a JS variable called _initialData.
# extract and parse it the same way as the search page.
data = re.findall(r"_initialData=(\{.+?\});", html)
if not data:
return {}
data = json.loads(data[0])
body = (data.get("autoOpenTwoPaneViewjobResponse") or {}).get("body") or {}
model = body.get("jobInfoWrapperModel", {}).get("jobInfoModel", {})
header = model.get("jobInfoHeaderModel", {})
description = model.get("sanitizedJobDescription", "")
review_model = header.get("companyReviewModel") or {}
rating_model = review_model.get("ratingsModel") or {}
raw_description = description if isinstance(description, str) else description.get("content", "")
return {
"full_description": strip_html(raw_description),
"detail_rating": rating_model.get("rating"),
"detail_review_count": rating_model.get("count"),
}
```
The parser uses `.get()` because detail pages don't always return the same nested fields. If a description, rating, or review count is missing, the function returns an empty string or `None` instead of stopping the scraper.
Next, add a function that writes the enriched job records to a CSV file.
```python
# ...
def save_to_csv(jobs, output_file):
if not jobs:
print("No jobs to save.")
return
with open(output_file, "w", newline="", encoding="utf-8") as f:
writer = csv.DictWriter(f, fieldnames=list(jobs[0].keys()))
writer.writeheader()
writer.writerows(jobs)
print("Saved " + str(len(jobs)) + " jobs to " + output_file)
```
Now create a loop that reads each `jobkey`, builds the detail page URL, fetches the detail page through Zenrows, parses the detail data, and appends the combined record to the `enriched` list. The loop starts with the first 10 jobs to keep the test run small; remove the slice when you're ready to enrich every listing.
```python
# ...
# q = keyword, l = location, filter = 0 disables deduplication
search_params = {
"q": "data engineer",
"l": "New York, NY",
"filter": 0,
}
search_url = "https://www.indeed.com/jobs?" + urlencode(search_params)
html = fetch_page(search_url)
page_data = parse_search_page(html)
print("Scraped " + str(len(page_data["results"])) + " jobs.")
enriched = []
# start with the first 10 jobs to keep the test run small
for job in page_data["results"][:10]:
jobkey = job.get("jobkey")
if not jobkey:
continue
# vjk opens the job in Indeed's side panel, which carries the full details
detail_url = "https://www.indeed.com/jobs?" + urlencode({**search_params, "vjk": jobkey})
detail_data = parse_job_page(fetch_page(detail_url))
enriched.append({
"title": job.get("displayTitle"),
"company": job.get("company"),
"location": job.get("formattedLocation"),
# not every listing shows a salary, so .get() returns None when it's missing
"salary": (job.get("salarySnippet") or {}).get("text"),
"salary_source": (job.get("salarySnippet") or {}).get("source"),
"job_type": ", ".join(get_job_types(job)),
"remote": job.get("remoteLocation"),
"posted": job.get("formattedRelativeTime"),
"company_rating": job.get("companyRating"),
"review_count": job.get("companyReviewCount"),
"jobkey": jobkey,
"full_description": detail_data.get("full_description", ""),
"detail_rating": detail_data.get("detail_rating"),
"detail_review_count": detail_data.get("detail_review_count"),
})
print("Enriched: " + str(job.get("displayTitle")) + " at " + str(job.get("company")))
save_to_csv(enriched, "indeed_jobs.csv")
```
Here is the full code:
```python
# pip3 install requests
import re
import json
import csv
import requests
from urllib.parse import urlencode
from html.parser import HTMLParser
# replace with your Zenrows API key from app.zenrows.com
APIKEY = ""
def fetch_page(url):
# mode="auto" activates Adaptive Stealth Mode
# wait_for holds the response until Indeed has rendered the job cards
params = {
"url": url,
"apikey": APIKEY,
"mode": "auto",
"js_instructions": json.dumps([{"wait_for": "[data-jk]"}]),
}
response = requests.get("https://api.zenrows.com/v1/", params=params)
response.raise_for_status()
return response.text
def parse_search_page(html):
# Indeed stores job data in a JS variable rather than plain HTML elements.
# use regex to extract the JSON block and parse it into a Python dict.
data = re.findall(
r'window\.mosaic\.providerData\["mosaic-provider-jobcards"\]=(\{.+?\});',
html
)
if not data:
return {"results": [], "meta": []}
data = json.loads(data[0])
return {
"results": data["metaData"]["mosaicProviderJobCardsModel"]["results"],
"meta": data["metaData"]["mosaicProviderJobCardsModel"]["tierSummaries"],
}
def get_job_types(job):
# job types live in the taxonomy attributes, under the "job-types" group
for group in job.get("taxonomyAttributes", []):
if group.get("label") == "job-types":
return [attribute["label"] for attribute in group.get("attributes", [])]
return []
def strip_html(raw):
# removes HTML tags from the job description and returns plain text.
# HTMLParser is part of Python's standard library, no extra install needed.
parser = HTMLParser()
parser.text = []
parser.handle_data = lambda data: parser.text.append(data)
parser.feed(raw)
return " ".join(" ".join(parser.text).split())
def parse_job_page(html):
# the open job's details sit in a JS variable called _initialData.
# extract and parse it the same way as the search page.
data = re.findall(r"_initialData=(\{.+?\});", html)
if not data:
return {}
data = json.loads(data[0])
body = (data.get("autoOpenTwoPaneViewjobResponse") or {}).get("body") or {}
model = body.get("jobInfoWrapperModel", {}).get("jobInfoModel", {})
header = model.get("jobInfoHeaderModel", {})
description = model.get("sanitizedJobDescription", "")
review_model = header.get("companyReviewModel") or {}
rating_model = review_model.get("ratingsModel") or {}
raw_description = description if isinstance(description, str) else description.get("content", "")
return {
"full_description": strip_html(raw_description),
"detail_rating": rating_model.get("rating"),
"detail_review_count": rating_model.get("count"),
}
def save_to_csv(jobs, output_file):
if not jobs:
print("No jobs to save.")
return
with open(output_file, "w", newline="", encoding="utf-8") as f:
writer = csv.DictWriter(f, fieldnames=list(jobs[0].keys()))
writer.writeheader()
writer.writerows(jobs)
print("Saved " + str(len(jobs)) + " jobs to " + output_file)
# q = keyword, l = location, filter = 0 disables deduplication
search_params = {
"q": "data engineer",
"l": "New York, NY",
"filter": 0,
}
search_url = "https://www.indeed.com/jobs?" + urlencode(search_params)
html = fetch_page(search_url)
page_data = parse_search_page(html)
print("Scraped " + str(len(page_data["results"])) + " jobs.")
enriched = []
# start with the first 10 jobs to keep the test run small
for job in page_data["results"][:10]:
jobkey = job.get("jobkey")
if not jobkey:
continue
# vjk opens the job in Indeed's side panel, which carries the full details
detail_url = "https://www.indeed.com/jobs?" + urlencode({**search_params, "vjk": jobkey})
detail_data = parse_job_page(fetch_page(detail_url))
enriched.append({
"title": job.get("displayTitle"),
"company": job.get("company"),
"location": job.get("formattedLocation"),
# not every listing shows a salary, so .get() returns None when it's missing
"salary": (job.get("salarySnippet") or {}).get("text"),
"salary_source": (job.get("salarySnippet") or {}).get("source"),
"job_type": ", ".join(get_job_types(job)),
"remote": job.get("remoteLocation"),
"posted": job.get("formattedRelativeTime"),
"company_rating": job.get("companyRating"),
"review_count": job.get("companyReviewCount"),
"jobkey": jobkey,
"full_description": detail_data.get("full_description", ""),
"detail_rating": detail_data.get("detail_rating"),
"detail_review_count": detail_data.get("detail_review_count"),
})
print("Enriched: " + str(job.get("displayTitle")) + " at " + str(job.get("company")))
save_to_csv(enriched, "indeed_jobs.csv")
```
When you run the code, the output is as follows.
```
Scraped 41 jobs.
Enriched: Data Engineer at BDG
Enriched: Data Engineer at DEPARTMENT OF SANITATION
Enriched: Analytics Engineer, Semantic Layer at Cloaked
Enriched: Associate Data Engineer at Aretove
Enriched: Data Engineer at Storm3
Enriched: Staff Real Time Software Engineer at TTM Technologies
Enriched: Executive Chef/Chef de Cuisine at Flinders Lane Kitchen & Bar
Enriched: Transfer as a Service (MFT) Operations Engineer at Comrise
Enriched: Data Engineer at Qualitate
Enriched: Engineer_Data Engineer_8 at Fractal Analytics
Saved 10 jobs to indeed_jobs.csv
```
Here is the start of the job description for the first job in the list, as saved in the `full_description` column.
```
Bustle Digital Group (BDG) is looking for a talented Data Engineer to join our growing data team. ...
```
The saved CSV now includes the full job description for each enriched listing, along with the main search result fields. All 10 detail requests returned a description.
## Extracting Salary Data at Scale
By now, your scraper saves salary as a raw string from `salarySnippet`. That works for a quick preview, but salary analysis needs separate fields for the amount, currency, source, and pay period. Otherwise, values like `$53 - $58 an hour`, `$105,000 - $145,000 a year`, and `$149,978 - $263,755 a year` all remain plain text.
Indeed returns salary data in two fields inside the search results JavaScript state object. The first field is `salarySnippet`, which stores the displayed salary text and the source of that salary.
```python
salary_snippet = job.get("salarySnippet", {})
{
"currency": "USD",
"salaryTextFormatted": False,
"source": "EXTRACTION",
"text": "$105,000 - $145,000 a year"
}
```
The `source` value tells you where the salary came from. `EMPLOYER_PROVIDED` means the employer submitted the salary figure with the listing. `EXTRACTION` means Indeed parsed the salary from the job description text, so the value depends on how the salary was written in the posting.
The second field is `extractedSalary`, which stores numeric salary values.
```python
extracted_salary = job.get("extractedSalary", {})
{
"max": 145000,
"min": 105000,
"type": "YEARLY"
}
```
`extractedSalary` gives you `min`, `max`, and `type` as separate fields. The `type` value tells you the pay period, such as `HOURLY` or `YEARLY`. When this field is present, it's better for salary analysis because the scraper doesn't need to parse numbers from a text string.
If you'd like to use this approach, replace the existing `enriched.append()` block in the enrichment loop with the code below.
```python
# ...
# code remains the same
# Indeed returns salary in two separate fields.
# salarySnippet contains a raw text string and a source indicator.
# extractedSalary contains structured numeric fields when present.
salary_snippet = job.get("salarySnippet") or {}
extracted_salary = job.get("extractedSalary") or {}
enriched.append({
"title": job.get("displayTitle"),
"company": job.get("company"),
"location": job.get("formattedLocation"),
"salary_text": salary_snippet.get("text"),
# EMPLOYER_PROVIDED = submitted by employer, EXTRACTION = parsed from job text
"salary_source": salary_snippet.get("source"),
"salary_currency": salary_snippet.get("currency"),
# structured numeric fields, more reliable when present
"salary_min": extracted_salary.get("min"),
"salary_max": extracted_salary.get("max"),
# pay period, such as "HOURLY" or "YEARLY"
"salary_type": extracted_salary.get("type"),
"job_type": ", ".join(get_job_types(job)),
"remote": job.get("remoteLocation"),
"posted": job.get("formattedRelativeTime"),
"company_rating": job.get("companyRating"),
"review_count": job.get("companyReviewCount"),
"jobkey": jobkey,
"full_description": detail_data.get("full_description", ""),
"detail_rating": detail_data.get("detail_rating"),
"detail_review_count": detail_data.get("detail_review_count"),
})
print("Enriched: " + str(job.get("displayTitle")) + " at " + str(job.get("company")))
save_to_csv(enriched, "indeed_jobs.csv")
```
The updated block keeps the displayed salary text and stores the parsed salary values when Indeed returns them. It also saves the salary source, so you can separate employer-submitted salaries from values Indeed extracted from the job text.
Here are four of the rows it saved:
| company | salary_text | salary_source | salary_min | salary_max | salary_type |
| --- | --- | --- | --- | --- | --- |
| BDG | $105,000 - $145,000 a year | EXTRACTION | 105000 | 145000 | YEARLY |
| DEPARTMENT OF SANITATION | $120,000 - $180,000 a year | EXTRACTION | 120000 | 180000 | YEARLY |
| TTM Technologies | $149,978 - $263,755 a year | EXTRACTION | 149978 | 263755 | YEARLY |
| Comrise | $53 - $58 an hour | EXTRACTION | 53 | 58 | HOURLY |
Because `salary_type` is its own column, you can compare hourly and yearly roles side by side. Multiply an hourly figure by the hours your analysis assumes per year before you put it next to annual salaries.
## Scraping Multiple Keywords and Locations
One search only covers one keyword in one place. Market research and prospecting usually need several of each, and the same job often matches more than one search. Loop over every keyword and location pair, and use the `jobkey` to keep each listing once.
```python
# ...
# fetch_page and parse_search_page remain the same
def scrape_many_searches(queries, locations, days=7):
jobs = {}
for query in queries:
for location in locations:
# fromage keeps each search to recent listings, filter=0 returns the full set
search_url = "https://www.indeed.com/jobs?" + urlencode({
"q": query,
"l": location,
"fromage": days,
"filter": 0,
})
results = parse_search_page(fetch_page(search_url))["results"]
# the same job can match several searches, so the jobkey keeps it once
new_jobs = 0
for job in results:
jobkey = job.get("jobkey")
if jobkey and jobkey not in jobs:
jobs[jobkey] = job
new_jobs += 1
print(query + " in " + location + ": " + str(len(results)) + " listings, " + str(new_jobs) + " new")
return list(jobs.values())
jobs = scrape_many_searches(
queries=["data engineer", "analytics engineer"],
locations=["New York, NY", "Austin, TX"],
)
print("Collected " + str(len(jobs)) + " unique jobs.")
```
When you run the code, the output is as follows.
```
data engineer in New York, NY: 42 listings, 42 new
data engineer in Austin, TX: 28 listings, 23 new
analytics engineer in New York, NY: 22 listings, 12 new
analytics engineer in Austin, TX: 17 listings, 9 new
Collected 86 unique jobs.
```
**Four searches returned 109 listings and 86 unique jobs.** The other 23 had already appeared in an earlier search, which is why [deduplication](/glossary/web-crawling/what-is-deduplication) by `jobkey` belongs in every Indeed pipeline. Narrow searches by location, job type, or posting age, as here, to cover a market in depth.
## Get Structured Job Data Without a Parser Using Zenrows Extract
If you don't want to maintain a regex against Indeed's JavaScript objects, [Zenrows Extract](/products/extract) returns the listings as structured JSON. Add `extract=auto` to the same request, and the response carries a `parsed` object next to the page HTML. There are no selectors or schema to write, and Extract keeps working when Indeed changes its layout.
```python
# pip3 install requests
import json
import requests
from urllib.parse import urlencode
# replace with your Zenrows API key from app.zenrows.com
APIKEY = ""
search_url = "https://www.indeed.com/jobs?" + urlencode({
"q": "data engineer",
"l": "New York, NY",
})
# extract="auto" returns the page as structured JSON instead of raw HTML
params = {
"url": search_url,
"apikey": APIKEY,
"mode": "auto",
"js_instructions": json.dumps([{"wait_for": "[data-jk]"}]),
"extract": "auto",
}
response = requests.get("https://api.zenrows.com/v1/", params=params)
response.raise_for_status()
listings = response.json()["parsed"]["job_listings"]
print("Extracted " + str(len(listings)) + " listings.")
# print the main fields of the first listing
first = listings[0]
print(json.dumps({key: first.get(key) for key in ("title", "company_name", "location", "job_key", "snippet")}, indent=4))
```
When you run the code, the output is as follows.
```
Extracted 16 listings.
{
"title": "Data Engineer",
"company_name": "BDG",
"location": "Hybrid work in New York, NY",
"job_key": "018b1c3eb568518f",
"snippet": "Experience working data generating frontends in React and TypeScript.\n Problem Solver & Innovator: Passionate about solving complex data challenges and improving…"
}
```
Use Extract when you want job cards with the least code, and the embedded JSON parser above when you need Indeed's own salary and taxonomy fields. The [Extract docs](https://docs.zenrows.com/extract/setup) cover the response format.
## Using Indeed Job Postings for Sales Prospecting and Lead Generation
A job posting can reveal the tools a company uses and the teams it's investing in. For example, a company selling CRM add-ons, data enrichment, or revenue operations tools can search for companies hiring `Salesforce administrator` roles, because those postings point to a company that runs Salesforce and is investing in it.
Let's create a pipeline that searches Indeed for that hiring signal, extracts company data from the embedded job cards object, deduplicates the results by company name, counts hiring volume, and exports a [lead list](/solutions/lead-enrichment) to a CSV file for outbound use.
```python
# pip3 install requests
import re
import json
import csv
import requests
from urllib.parse import urlencode
# replace with your Zenrows API key
APIKEY = ""
def fetch_page(url):
# mode="auto" activates Adaptive Stealth Mode
# wait_for holds the response until Indeed has rendered the job cards
params = {
"url": url,
"apikey": APIKEY,
"mode": "auto",
"js_instructions": json.dumps([{"wait_for": "[data-jk]"}]),
}
response = requests.get("https://api.zenrows.com/v1/", params=params)
response.raise_for_status()
return response.text
def parse_search_page(html):
# indeed stores job data in a JS variable rather than plain HTML elements
# use regex to extract the JSON block and parse it into a Python dict
data = re.findall(
r'window\.mosaic\.providerData\["mosaic-provider-jobcards"\]=(\{.+?\});',
html
)
if not data:
return []
data = json.loads(data[0])
return data["metaData"]["mosaicProviderJobCardsModel"]["results"]
def make_search_url(query, location):
return "https://www.indeed.com/jobs?" + urlencode({
"q": query,
"l": location,
"filter": 0,
})
def build_prospect_list(keyword, location, output_file="prospects.csv"):
print("Searching Indeed for " + keyword + " in " + location + "...")
html = fetch_page(make_search_url(keyword, location))
results = parse_search_page(html)
print("Found " + str(len(results)) + " listings.")
# count hiring volume per company and deduplicate by company name
company_data = {}
for job in results:
company = job.get("company")
if not company:
continue
if company not in company_data:
company_data[company] = {
"company": company,
"location": job.get("formattedLocation"),
"hiring_volume": 0,
"sample_role": job.get("displayTitle"),
"job_url": "https://www.indeed.com/viewjob?jk=" + str(job.get("jobkey")),
"company_rating": job.get("companyRating"),
"remote": job.get("remoteLocation"),
"posted": job.get("formattedRelativeTime"),
}
company_data[company]["hiring_volume"] += 1
# sort by hiring volume descending, so companies posting more roles rank higher
prospects = sorted(
company_data.values(),
key=lambda x: x["hiring_volume"],
reverse=True
)
print("Found " + str(len(prospects)) + " unique companies hiring for " + keyword + ".")
if prospects:
with open(output_file, "w", newline="", encoding="utf-8") as f:
writer = csv.DictWriter(f, fieldnames=list(prospects[0].keys()))
writer.writeheader()
writer.writerows(prospects)
print("Prospect list saved to " + output_file)
return prospects
if __name__ == "__main__":
# companies hiring Salesforce administrators are investing in their CRM,
# a buying signal for CRM add-ons, data and RevOps tooling vendors.
build_prospect_list(
keyword="Salesforce administrator",
location="United States",
output_file="crm_prospects.csv",
)
```
The `make_search_url()` function builds the Indeed URL from a keyword and location. In this example, the keyword is a role tied to one platform, so the search targets companies that run that platform rather than everyone hiring in sales operations.
The `build_prospect_list()` function then fetches the results page, parses the embedded job cards data, and groups the listings by company name. This deduplicates the output because each company appears once in the CSV, even when it has several matching job listings. The `hiring_volume` value increases each time another matching listing for the same company appears.
The code finally sorts the rows by hiring volume before saving the results to a CSV file. This makes companies with more matching roles appear first.
When you run the code, the results are as shown below.
Terminal results:
```
Searching Indeed for Salesforce administrator in United States...
Found 45 listings.
Found 42 unique companies hiring for Salesforce administrator.
Prospect list saved to crm_prospects.csv
```
The first rows of the saved CSV file:
| company | location | hiring_volume | sample_role | remote | posted |
| --- | --- | --- | --- | --- | --- |
| Opensity Solutions | Cleveland, OH 44113 | 3 | Client Account Manager - Word Processing | False | Just posted |
| Leidos | Reston, VA 20190 | 2 | Computer Support Analyst | False | Just posted |
| VS Techsystems | Remote | 1 | Salesforce Administrator | True | 4 days ago |
| Debt Space LLC | Remote | 1 | Salesforce Administrator | True | 30+ days ago |
| Zuma Payroll & Processing Inc. | Melville, NY 11747 | 1 | Salesforce Admin | False | Just posted |
Indeed's search matches more than the job title, so some top rows mention Salesforce inside a broader role. Check `sample_role` before a row goes into a sequence, or filter titles in code.
Congratulations 🎉 Your Indeed [lead generation pipeline](/blog/lead-scraper) successfully scraped live job postings, deduplicated them by company, counted hiring volume, and saved a lead list to a CSV file. You can now use job postings as buying signals for outbound sales workflows.
If you're running go-to-market (GTM) workflows in Clay, Zenrows [integrates with Clay](/integrations/clay) natively. Follow our [step-by-step setup guide](https://docs.zenrows.com/integrations/clay) to send scraped Indeed data directly into your Clay table without any additional code.
## Best Practices for Scraping Indeed at Scale
Once you scale your Indeed scraper, you'll need to implement several safeguards to make sure it stays reliable.
- **Run detail pages concurrently, or as one Batch job**: Enriching listings with full descriptions means sending one scrape request per `jobkey`. If you process those pages one at a time, large runs will be slow. [Use `asyncio` with Zenrows](/blog/speed-up-web-scraping-with-concurrency-in-python) to run several scrape requests concurrently, or submit the whole list of detail URLs to [Zenrows Batch](/products/batch), which runs them as one managed job with retries and per-URL results. The [large-scale scraping guide](/blog/large-scale-web-scraping-zenrows-batch) walks through a Batch job end to end.
- **Deduplicate by job ID**: Indeed can show the same job across multiple searches, locations, or related keyword queries. Use the `jobkey` as the deduplication key because it identifies a specific listing. Store seen `jobkey` values in a set before saving records, then skip any listing that already exists in the current run or in your database.
- **Use freshness filters for incremental scraping**: The `fromage` parameter lets you filter results by posting age. For a daily job, use a narrow value such as `fromage=1` or `fromage=2` so the scraper collects recent listings instead of crawling the same full result set every time. This reduces duplicate data, request volume, and cleanup work.
- **Check for the job cards object on every response**: A page without `mosaic-provider-jobcards` has no job data, whatever its status code. Treat an empty result as a signal to inspect the HTML, and log it, so a page change never passes silently as "no jobs today."
- **Choose the right output format**: Match the export format to the workflow that will use the data. CSV is a good fit when people will review the output in Excel, Google Sheets, or sales operations tools. JSON works better when another service, API, or data pipeline will process the records. SQLite is useful for local analysis because it lets you query, deduplicate, and compare repeat runs without setting up a separate database server. [JSON vs JSONL vs CSV vs XML](/glossary/web-data-extraction/json-vs-jsonl-vs-csv-vs-xml) compares the formats.
## Common Errors and Fixes
Even after the scraper works, Indeed can still return missing data, capped result sets, or blocked responses when the request settings or page structure change. Use the list below to diagnose the most common issues.
- [**Cloudflare challenge page**](/blog/flaresolverr) **returned instead of jobs**: Confirm `mode=auto` is set in your request. Adaptive Stealth Mode detects challenge pages and escalates automatically, so a challenge page in your output almost always means a request that went out without it.
- **Empty job list with a 200 response, and the HTML is a loading screen**: Indeed returned the page before its JavaScript built the job cards. Keep the `wait_for` instruction for `[data-jk]` in `js_instructions`, so Zenrows waits for the cards before returning the HTML.
- **Salary field is always None**: Not every listing shows a salary, so some search result records won't include salary data. Use `.get()` for salary fields and save the job record even when the salary is missing.
- **Empty job list despite a full page**: A 200 response only means the request succeeded. If the job list is empty, Indeed may have changed the JavaScript variable that stores the job cards. To find the current variable name, right-click anywhere on the Indeed search page and select View Page Source. Search for `providerData`, locate the current variable assignment, and update the regex in your parser to match it.
- **Detail fields come back empty**: Indeed moved job details into the side panel, under `autoOpenTwoPaneViewjobResponse`. Build the detail URL from the search URL plus `vjk=`, as in the enrichment code above.
- [**`429` rate limit**](/blog/429-too-many-requests): A `429` response means the site received too many requests in a short period. Keep `mode=auto` enabled so premium proxies are applied automatically when per-IP throttling is detected, and add a retry with a short backoff in your own code, or run the URLs through Batch, which retries for you.
When debugging, check the returned HTML first. If the expected job data isn't in the response, fix the request settings or update the parser before changing the rest of the scraper.
## Is It Legal to Scrape Indeed?
Collecting publicly available job listings is generally lawful in the United States. In [hiQ Labs v. LinkedIn](https://calawyers.org/privacy-law/ninth-circuit-holds-data-scraping-is-legal-in-hiq-v-linkedin/), the Ninth Circuit held that scraping public pages likely doesn't violate the Computer Fraud and Abuse Act. The same case later found hiQ in breach of LinkedIn's user agreement, and Indeed's terms of service restrict automated access, so the contract side still applies. Keep to public listings, leave out personal data such as recruiter names, respect [robots.txt](/glossary/web-crawling/what-is-robots-txt) and sensible request rates, and check your use case with counsel before you build a product on the data.
## Conclusion
In this article, you've learned how to scrape Indeed job listings with Python and Zenrows, from search results to job detail enrichment. You also learned how to extract salary data, cover several keywords and locations, get structured listings with Extract, and use job postings as sales signals for prospecting workflows.
Scraping Indeed at scale is harder when the site returns JS challenges, renders its listings in the browser, or rate limits your scraper. Zenrows removes that overhead: [Fetch](/products/fetch) handles JavaScript rendering, proxy routing, and anti-bot bypass in a single API call, Extract turns the page into JSON, and Batch runs your whole list of detail pages as one job.
[Start building free](https://app.zenrows.com/register?prod=universal_scraper) with 5,000 credits every month, or [speak with sales](/contact).
## FAQ
### Is There an API for Indeed?
Not for reading job listings. Indeed has retired its public Publisher Job Search API and no longer issues keys for it. Its current developer APIs are for employers and ATS partners who post jobs and manage applications, and they require Indeed's approval. To collect job listings programmatically, you scrape Indeed's public search and job pages.
### Is It Legal to Scrape Indeed?
Scraping publicly available job listings is generally lawful in the United States. The Ninth Circuit's hiQ v. LinkedIn ruling held that scraping public pages likely doesn't violate the Computer Fraud and Abuse Act. Indeed's terms of service still restrict automated access, so keep to public data, avoid personal information, and get legal advice for commercial use.
### Can Indeed Detect Scraping?
Yes. Indeed uses Cloudflare to detect automated traffic through JS challenge pages, TLS fingerprinting, and request patterns, and plain Python requests get a "Security Check" page with a 403 status. To scrape Indeed reliably, use a web scraping API like Zenrows that handles anti-bot bypass and JavaScript rendering automatically with `mode=auto`.
### Why Does My Indeed Scraper Return an Empty Page?
Indeed renders its search results in the browser, so the first HTML it sends is a loading shell without job cards. Render the page and wait for the cards before reading it. With Zenrows, add a `wait_for` JavaScript instruction for the `[data-jk]` selector alongside `mode=auto`.
### How Do I Get the Full Job Description From Indeed?
Take the `jobkey` from the search results and add it to the search URL as `vjk=`. Indeed then opens the job in its side panel, and the page's `_initialData` object carries the full description under `autoOpenTwoPaneViewjobResponse`. The enrichment code in this guide does this for each listing.
### How Do I Scrape Indeed for Free?
Use a web scraping API with a free plan. Zenrows' free plan gives you 5,000 credits every month with no credit card required, enough to scrape a set of search pages and their job detail pages while you build and test your scraper.
### How Do I Use Indeed Job Data for Sales Prospecting?
To use Indeed job data for sales prospecting, search Indeed for job titles tied to the technology your product targets. Extract company names, locations, and hiring volume from the results. Then deduplicate by company name and export the data to a CSV file. Companies posting multiple roles for the same technology are actively investing in that stack and are worth reaching out to.