# Visual Basic Web Scraping: Tutorial 2026
> Learn the essentials of Visual Basic web scraping: Setup, IDE selection, and using Html Agility Pack for effective data extraction.
Source: https://www.zenrows.com/blog/visual-basic-web-scraping
Building a Visual Basic web scraping script is not only possible but advisable too. That's due to the interoperability of the language with .NET and its simple syntax.
In this guided tutorial, you'll learn how to do web scraping with Visual Basic using Html Agility Pack. Let's dive in!
## Can You Scrape Websites With Visual Basic?
Yes, you can scrape websites with Visual Basic!
Most developers tend to prefer Python or JavaScript for web scraping because of their extensive ecosystems. While it may not be the best language for web scraping, Visual Basic is a viable option for at least two good reasons:
1. An intuitive and easy-to-understand syntax, which is excellent when it comes to scripting.
2. Its interoperability with the .NET ecosystem.
This means using popular C# scraping libraries with a straightforward syntax. Thanks to its versatility, ease of use, and integration capabilities, Visual Basic is a viable choice for web scraping!
## Prerequisites
Prepare your VB.NET environment for web scraping with Html Agility Pack.
### Set Up the Environment
Visual Basic requires .NET to work. So, ensure you have the latest version of the .NET SDK installed on your machine. As of this writing, that's .NET 8.0. [Download the installer](https://dotnet.microsoft.com/en-us/download/dotnet/8.0), run it, and follow the wizard.
You'll also need a .NET IDE to go through this tutorial. [Visual Studio 2022 Community Edition](https://visualstudio.microsoft.com/vs/community/) is a great option, especially for enterprises. If you prefer a lighter IDE, [Visual Studio Code with the .NET extensions](https://code.visualstudio.com/docs/languages/dotnet) will be perfect.
Otherwise, set up your environment directly with the [.NET Coding Pack](https://code.visualstudio.com/docs/languages/dotnet#_net-coding-pack). That includes the .NET SDK, Visual Studio Code, and the essential .NET extensions.
Awesome! Your Visual Basic environment is good to go.
### Create a Visual Basic Project
Create a `VisualBasicScraper` folder for your Visual Basic .NET project and enter it in the terminal:
```nginx
mkdir VisualBasicScraper
cd VisualBasicScraper
```
Inside the empty directory, use this command to set up a new Visual Basic [.NET console project](https://learn.microsoft.com/en-us/dotnet/core/tools/dotnet-new-sdk-templates#console):
```nginx
dotnet new console --framework net8.0 --language VB
```
`VisualBasicScraper` will now contain a .NET 8 console application in Visual Basic. Load the project folder in Visual Studio Code and take a look at the `Program.vb` file:
```
Imports System
Module Program
Sub Main(args As String())
Console.WriteLine("Hello World!")
End Sub
End Module
```
This is the main file of your Visual Basic project that you'll soon override with some scraping logic.
Launch the script to verify that it works via the command below:
```nginx
dotnet run
```
If all goes as expected, you'll see in the terminal:
```nginx
Hello World!
```
Well done! Get ready to transform that script into a Visual Basic web scraping script.
> **Skip the blocks.** [Try Zenrows free](/) and get clean web data without the anti-bot fight.
## Tutorial: How to Do Web Scraping With Visual Basic?
The scraping target will be [Scrapingcourse](https://www.scrapingcourse.com/ecommerce/), a demo e-commerce site with a paginated list of products. The goal of the Visual Basic scraper you'll build is to extract all product data from this platform:
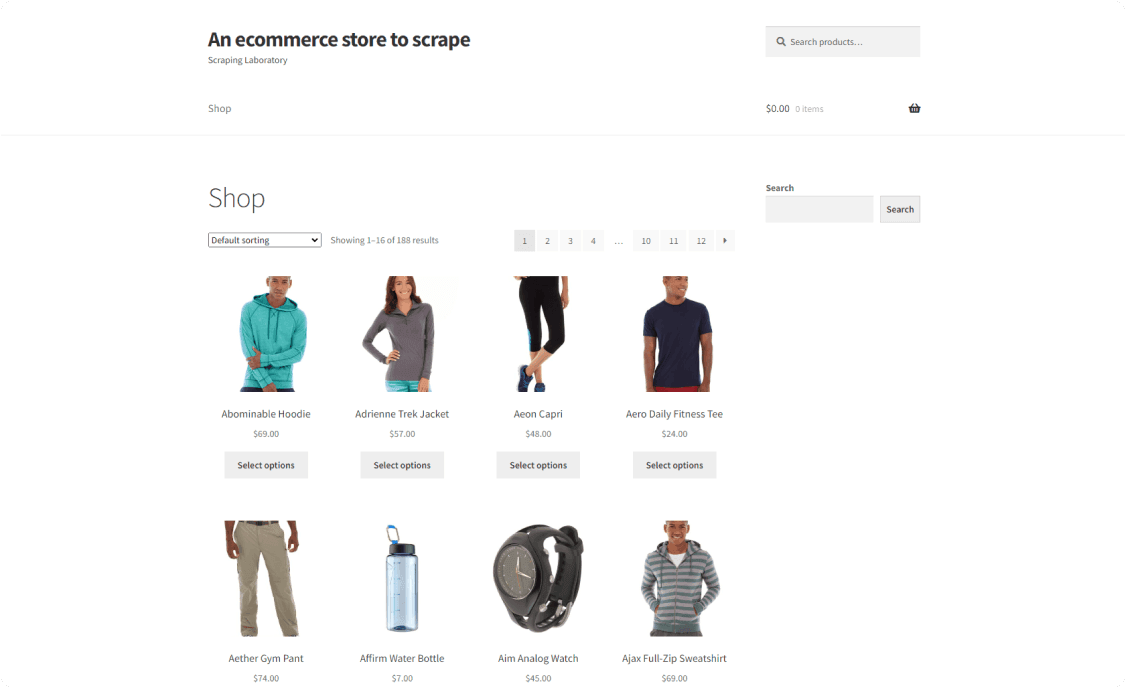
Get ready to perform web scraping with Visual Basic!
### Step 1: Scrape Your Target Page
The best way to link to a Web page and retrieve its HTML source code is to use an external library. [Html Agility Pack](https://html-agility-pack.net/) (HAP) is the most popular .NET library for dealing with HTML documents. It offers a flexible API to download a web page, parse it, and extract data from it.
Install HAP by adding the NuGet [`HtmlAgilityPack`](https://www.nuget.org/packages/HtmlAgilityPack/) package to your project's dependencies:
```nginx
dotnet add package HtmlAgilityPack
```
This will take a while so be patient while NuGet installs the library.
Next, add the following line on top of your `Program.vb` file to import Html Agility Pack:
```
Imports HtmlAgilityPack
```
Inside `Main()`, create a `HtmlWeb` instance, and use the [`Load()`](https://html-agility-pack.net/from-web) method to download the target page:
```
' initialize the HAP HTTP client
Dim web As New HtmlWeb()
' connect to target page
Dim document = web.Load("https://www.scrapingcourse.com/ecommerce/")
```
Behind the scenes, HAP will:
1. Perform an HTTP `GET` request to the specified URL.
2. Retrieve the HTML document returned by the server.
3. Parse it and generate an `HtmlDocument` object that exposes methods to scrape data from it.
Then, use the `document.DocumentNode` attribute to access the raw HTML of the page. Print it with `Console.WriteLine()`:
```
Console.WriteLine(document.DocumentNode.OuterHtml)
```
Update your `Program.vb` file with the following code:
```
Imports HtmlAgilityPack
Public Module Program
Public Sub Main()
' initialize the HAP HTTP client
Dim web As New HtmlWeb()
' connect to target page
Dim document = web.Load("https://www.scrapingcourse.com/ecommerce/")
' print the HTML source code
Console.WriteLine(document.DocumentNode.OuterHtml)
End Sub
End Module
```
Execute the script, and it'll log the following output:
```nginx
Ecommerce Test Site to Learn Web Scraping – ScrapingCourse.com
Showing 1–16 of 188 results
```
Excellent! Your Visual Basic scraping script retrieves the target page as desired. It's time to collect some data from it.
### Step 2: Extract the HTML Data for One Product
To scrape a web page, you must define an effective node selection strategy. That allows you to select the HTML elements of interest from the page and get data from them. To define it, you first have to inspect the HTML source code of the web page.
Visit the target page of your script in the browser and inspect a product HTML node with the DevTools:
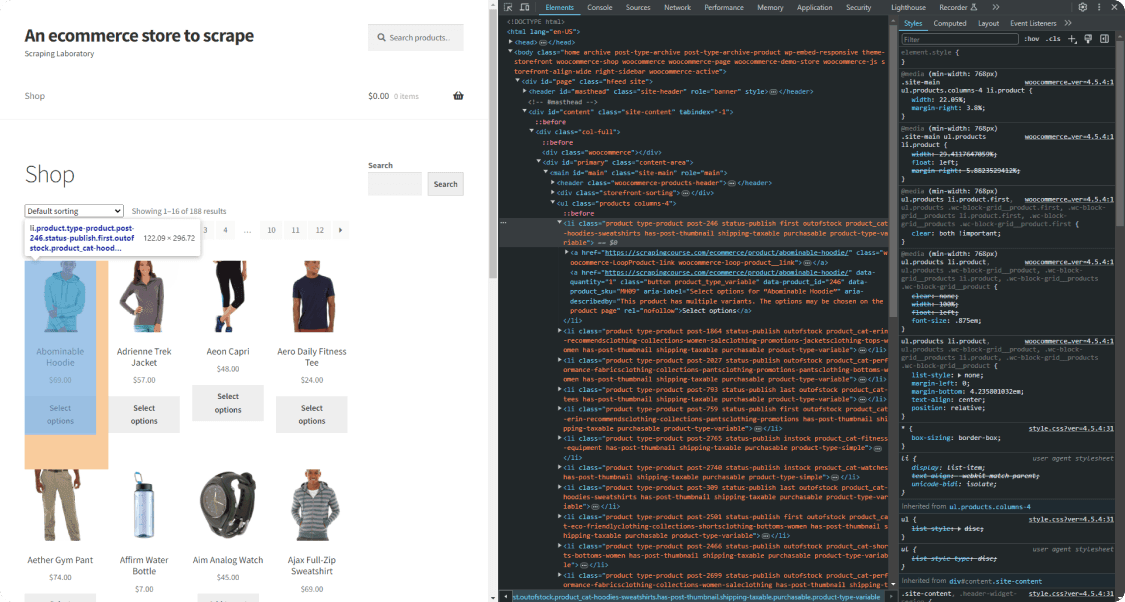
Take a look at the HTML code and notice that you can select each product node with this CSS selector:
```
li.product
```
> **Info**
>
> `li` is the tag of the HTML element, while `product` is its class.
Selected a product node, you can then extract:
- The URL from the `` node.
- The image URL from the `` node.
- The price from the `` node.
Before diving into the scraping logic, keep in mind that HAP natively supports [XPath](https://developer.mozilla.org/en-US/docs/Web/XPath) and [XSLT](https://developer.mozilla.org/en-US/docs/Web/XSLT). When it comes to selecting HTML elements from the DOM, you probably want to use [CSS Selectors](https://developer.mozilla.org/en-US/docs/Web/CSS/CSS_selectors). Learn why in your [XPath vs CSS Selector](/blog/xpath-vs-css-selector) guide.
Thus, install the [HtmlAgilityPack CSS Selector](https://github.com/hcesar/HtmlAgilityPack.CssSelector) extension via the NuGet [`HtmlAgilityPack.CssSelectors`](https://www.nuget.org/packages/HtmlAgilityPack.CssSelectors) library:
```nginx
dotnet add package HtmlAgilityPack.CssSelectors
```
This package adds the two methods below to `document.DocumentNode` object:
- `QuerySelector()` to get the first HTML node that matches the CSS selector passed as an argument.
- `QuerySelectorAll()` to find all nodes matching the given CSS selector.
Use them to implement the web scraping Visual Basic logic as follows:
```
' get the first HTML product node on the page
Dim productHTMLElement = document.DocumentNode.QuerySelector("li.product")
' scrape the data of interest from it and log it
Dim name = HtmlEntity.DeEntitize(productHTMLElement.QuerySelector("h2").InnerText)
Dim url = HtmlEntity.DeEntitize(productHTMLElement.QuerySelector("a").Attributes("href").Value)
Dim image = HtmlEntity.DeEntitize(productHTMLElement.QuerySelector("img").Attributes("src").Value)
Dim price = HtmlEntity.DeEntitize(productHTMLElement.QuerySelector(".price").InnerText)
```
`QuerySelector()` applies the specified CSS selector and gets the desired node. `Attributes` helps you find an HTML attribute while `Value` enables you to access its value.
> **Info**
>
> Each scraping line is wrapped with `HtmlEntity.DeEntitize()` to replace known [HTML entities](https://developer.mozilla.org/en-US/docs/Glossary/Entity).
You can then print the scraped data in the terminal with:
```
Console.WriteLine("Product URL: " & url)
Console.WriteLine("Product Image: " & image)
Console.WriteLine("Product Name: " & name)
Console.WriteLine("Product Price: " & price)
```
`Program.vb` will now contain:
```
Imports HtmlAgilityPack
Public Module Program
Public Sub Main()
' initialize the HAP HTTP client
Dim web As New HtmlWeb()
' connect to target page
Dim document = web.Load("https://www.scrapingcourse.com/ecommerce/")
' get the first HTML product node on the page
Dim productHTMLElement = document.DocumentNode.QuerySelector("li.product")
' scrape the data of interest from it and log it
Dim name = HtmlEntity.DeEntitize(productHTMLElement.QuerySelector("h2").InnerText)
Dim url = HtmlEntity.DeEntitize(productHTMLElement.QuerySelector("a").Attributes("href").Value)
Dim image = HtmlEntity.DeEntitize(productHTMLElement.QuerySelector("img").Attributes("src").Value)
Dim price = HtmlEntity.DeEntitize(productHTMLElement.QuerySelector("span").InnerText)
Console.WriteLine("Product Name: " & name)
Console.WriteLine("Product URL: " & url)
Console.WriteLine("Product Image: " & image)
Console.WriteLine("Product Price: " & price)
End Sub
End Module
```
Launch it, and it'll print:
```nginx
Product URL: https://www.scrapingcourse.com/ecommerce/product/abominable-hoodie/
Product Image: https://www.scrapingcourse.com/ecommerce/wp-content/uploads/2024/03/mh09-blue_main-324x324.jpg
Product Name: Abominable Hoodie
Product Price: $69.00
```
Wonderful! Now, learn how to scrape all elements on the page in the next section.
### Step 3: Extract Multiple Products Data
Before you extend the scraping logic, you need a data structure where to store the scraped data. For this reason, define a new class called `Product`:
```
Public Class Product
Public Property Url As String
Public Property Image As String
Public Property Name As String
Public Property Price As String
End Class
```
In `Main()`, initialize a new `Product` list. This is where you'll store the data objects populated with the data extracted from the page:
```
Dim products As New List(Of Product)()
```
Now, use `QuerySelectorAll()` instead of `QuerySelector()` to get all product elements on the page. Iterate over them, apply the scraping logic, instantiate a `Product` object, and add it to the list:
```
' select all HTML product nodes
Dim productHTMLElements = document.DocumentNode.QuerySelectorAll("li.product")
' iterate over the list of product HTML elements
For Each productHTMLElement In productHTMLElements
' scraping logic
Dim url = HtmlEntity.DeEntitize(productHTMLElement.QuerySelector("a").Attributes("href").Value)
Dim image = HtmlEntity.DeEntitize(productHTMLElement.QuerySelector("img").Attributes("src").Value)
Dim name = HtmlEntity.DeEntitize(productHTMLElement.QuerySelector("h2").InnerText)
Dim price = HtmlEntity.DeEntitize(productHTMLElement.QuerySelector("span").InnerText)
' instantiate a new Product object with the scraped data
' and add it to the list
Dim product = New Product With {
.Url = url,
.Image = image,
.Name = name,
.Price = price
}
products.Add(product)
Next
```
Print the scraped data to make sure the Visual Basic web scraping logic works:
```
For Each product In products
Console.WriteLine("Product URL: " & product.url)
Console.WriteLine("Product Image: " & product.image)
Console.WriteLine("Product Name: " & product.name)
Console.WriteLine("Product Price: " & product.price)
Console.WriteLine()
Next
```
This is the code of your current scraper:
```
Imports HtmlAgilityPack
Public Module Program
' define a custom class for the data to scrape
Public Class Product
Public Property Url As String
Public Property Image As String
Public Property Name As String
Public Property Price As String
End Class
Public Sub Main()
' initialize the HAP HTTP client
Dim web As New HtmlWeb()
' connect to target page
Dim document = web.Load("https://www.scrapingcourse.com/ecommerce/")
' where to store the scraped data
Dim products As New List(Of Product)()
' select all HTML product nodes
Dim productHTMLElements = document.DocumentNode.QuerySelectorAll("li.product")
' iterate over the list of product HTML elements
For Each productHTMLElement In productHTMLElements
' scraping logic
Dim url = HtmlEntity.DeEntitize(productHTMLElement.QuerySelector("a").Attributes("href").Value)
Dim image = HtmlEntity.DeEntitize(productHTMLElement.QuerySelector("img").Attributes("src").Value)
Dim name = HtmlEntity.DeEntitize(productHTMLElement.QuerySelector("h2").InnerText)
Dim price = HtmlEntity.DeEntitize(productHTMLElement.QuerySelector("span").InnerText)
' instantiate a new Product object with the scraped data
' and add it to the list
Dim product = New Product With {
.Url = url,
.Image = image,
.Name = name,
.Price = price
}
products.Add(product)
Next
' log the scraped data in the terminal
For Each product In products
Console.WriteLine("Product URL: " & product.url)
Console.WriteLine("Product Image: " & product.image)
Console.WriteLine("Product Name: " & product.name)
Console.WriteLine("Product Price: " & product.price)
Console.WriteLine()
Next
End Sub
End Module
```
Run it, and it'll produce the following output:
```nginx
Product URL: https://www.scrapingcourse.com/ecommerce/product/abominable-hoodie/
Product Image: https://www.scrapingcourse.com/ecommerce/wp-content/uploads/2024/03/mh09-blue_main-324x324.jpg
Product Name: Abominable Hoodie
Product Price: £69.00
' omitted for brevity...
Product URL: https://www.scrapingcourse.com/ecommerce/product/artemis-running-short/
Product Image: https://www.scrapingcourse.com/ecommerce/wp-content/uploads/2024/03/wsh04-black_main-324x324.jpg
Product Name: Artemis Running Short
Product Price: $45.00
```
Here we go! The scraped objects contain the data of interest.
### Step 4: Convert Scraped Data Into a CSV File
You can convert the collected data to CSV with the Visual Basic Sytem API. At the same time, using a library will make everything much easier.
[CsvHelper](https://joshclose.github.io/CsvHelper/) is a powerful .NET library for reading and writing CSV files. Install it by adding the NuGet [`CsvHelper`](https://www.nuget.org/packages/CsvHelper/) package to your project's dependencies:
```nginx
dotnet add package CsvHelper
```
Next, add the `CsvHelper` and the other required imports to your `Program.vb` file:
```
Imports CsvHelper
Imports System.Globalization
Imports System.IO
```
Initialize a CSV output file with `StreamWriter()` and populate it with `CsvHelper`. Use [`WriteRecords()`](https://joshclose.github.io/CsvHelper/getting-started/#writing-a-csv-file) to convert the `Product` objects to CSV records:
```
Using writer As New StreamWriter("products.csv")
Using csv As New CsvWriter(writer, CultureInfo.InvariantCulture)
csv.WriteRecords(products)
End Using
End Using
```
> **Info**
>
> The [`CultureInfo.InvariantCulture`](https://learn.microsoft.com/en-us/dotnet/api/system.globalization.cultureinfo.invariantculture?view=net-8.0) argument ensures that any software can parse the produced CSV file, regardless of the user's local settings.
Put it all together, and you'll get:
```
Imports HtmlAgilityPack
Imports CsvHelper
Imports System.Globalization
Imports System.IO
Public Module Program
' define a custom class for the data to scrape
Public Class Product
Public Property Url As String
Public Property Image As String
Public Property Name As String
Public Property Price As String
End Class
Public Sub Main()
' initialize the HAP HTTP client
Dim web As New HtmlWeb()
' connect to target page
Dim document = web.Load("https://www.scrapingcourse.com/ecommerce/")
' where to store the scraped data
Dim products As New List(Of Product)()
' select all HTML product nodes
Dim productHTMLElements = document.DocumentNode.QuerySelectorAll("li.product")
' iterate over the list of product HTML elements
For Each productHTMLElement In productHTMLElements
' scraping logic
Dim url = HtmlEntity.DeEntitize(productHTMLElement.QuerySelector("a").Attributes("href").Value)
Dim image = HtmlEntity.DeEntitize(productHTMLElement.QuerySelector("img").Attributes("src").Value)
Dim name = HtmlEntity.DeEntitize(productHTMLElement.QuerySelector("h2").InnerText)
Dim price = HtmlEntity.DeEntitize(productHTMLElement.QuerySelector("span").InnerText)
' instantiate a new Product object with the scraped data
' and add it to the list
Dim product = New Product With {
.Url = url,
.Image = image,
.Name = name,
.Price = price
}
products.Add(product)
Next
' export the scraped data to CSV
Using writer As New StreamWriter("products.csv")
Using csv As New CsvWriter(writer, CultureInfo.InvariantCulture)
' populate the CSV file
csv.WriteRecords(products)
End Using
End Using
End Sub
End Module
```
Launch the Visual Basic web scraping script:
```nginx
dotnet run
```
Wait for the script to finish, and a `products.csv` file will appear in the project's folder. Open it, and you'll see:
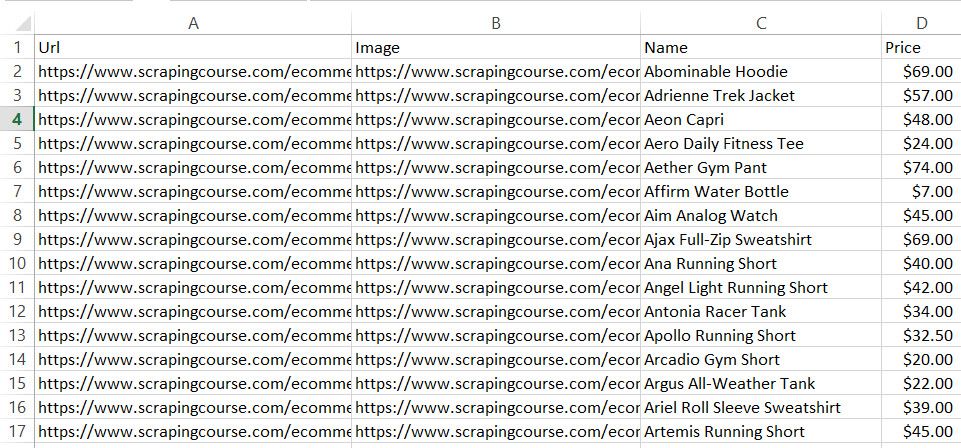
Et voilà! You just performed web scraping with Visual Basic!
## Advanced Web Scraping Techniques With Visual Basic
Now that you’ve seen the basics, dig into more advanced Visual Basic web scraping techniques.
### Web Crawling in Visual Basic: Scrape Multiple Pages
Currently, the output CSV contains a record for each product on the home page of the target site. To scrape all products, you must perform web crawling. That involves discovering web pages and getting data from each of them. Find out more in our guide on [web crawling vs web scraping](/blog/web-crawling-vs-web-scraping).
Here is what you need to do:
1. Visit a page.
2. Discover new URLs from pagination link elements and add them to a queue.
3. Repeat the cycle with a new page extracted from the queue.
This loop stops only when there are no more pages to discover. In other words, it'll stop when the Visual Basic scraping script has visited all pagination pages. Since this is just a demo script, we'll limit the pages to scrape to 5 to avoid making too many requests to the target site.
You already know how to visit a page with Html Agility Pack. So, learn how to extract URLs from the pagination links. Inspect these HTML elements on the page as a first step:
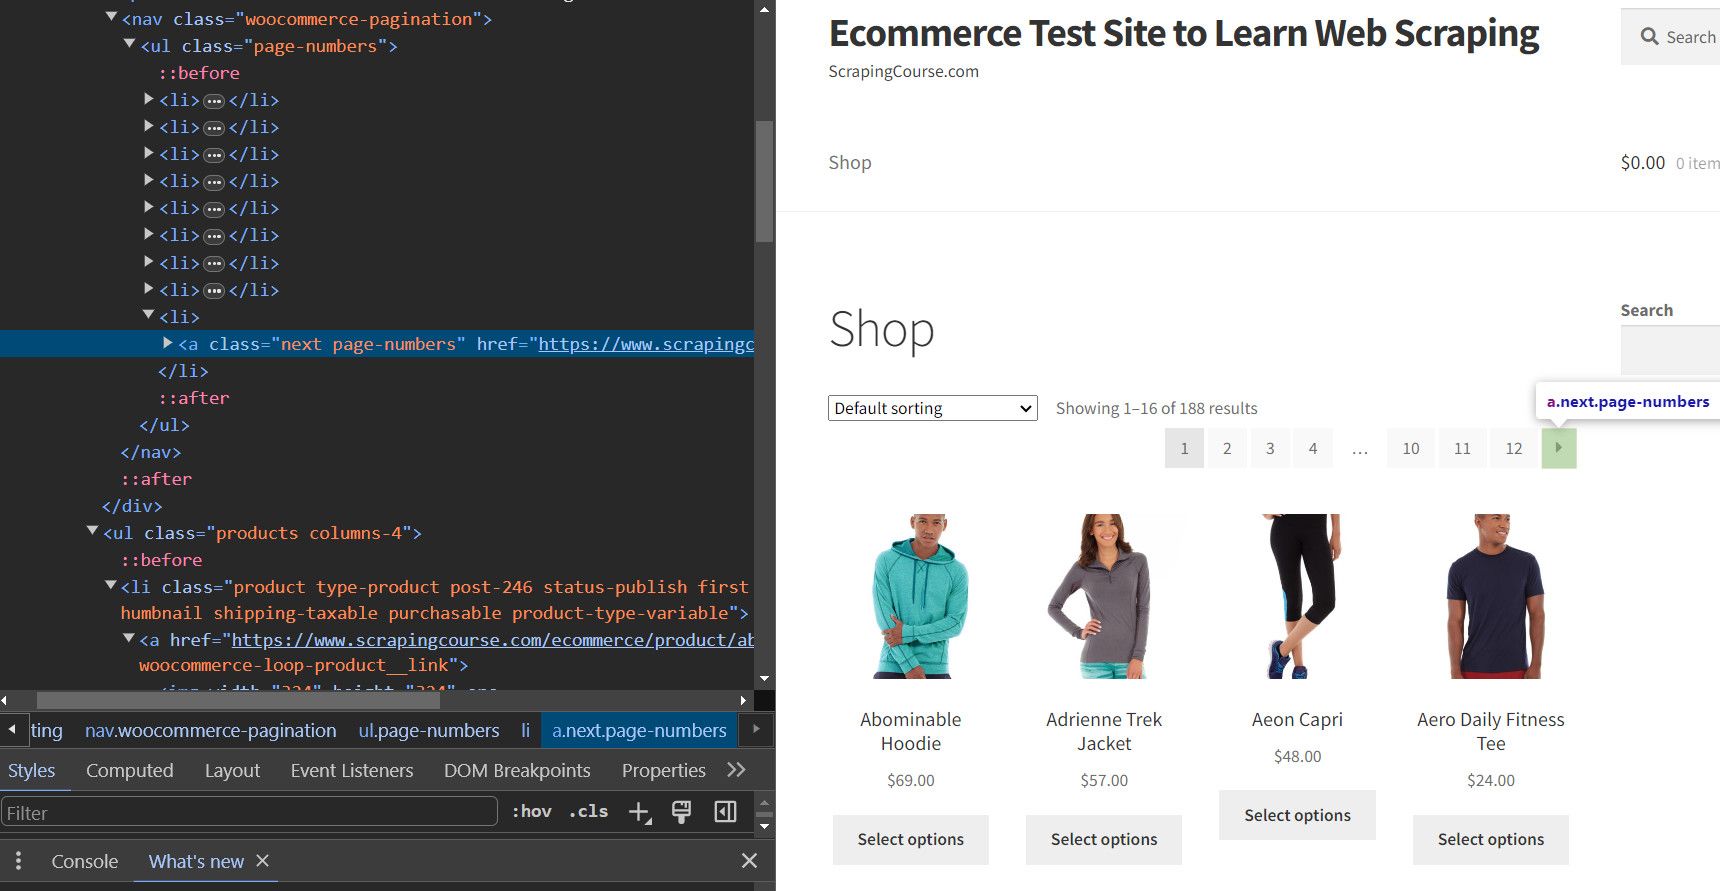
Note that you can select each pagination link with this CSS selector:
```
a.page-numbers
```
To avoid landing on the same page twice while crawling the site, you'll need two extra data structures:
- `pagesDiscovered`: A `HashSet` containing the URLs discovered by the crawling logic.
- `pagesToScrape`: A `Queue` with the URLs of the pages to visit soon.
Initialize both with the URL of the first pagination page:
```
Dim firstPageToScrape = "https://www.scrapingcourse.com/ecommerce/page/1/"
Dim pagesDiscovered As New HashSet(Of String) From {firstPageToScrape}
Dim pagesToScrape As New Queue(Of String)()
pagesToScrape.Enqueue(firstPageToScrape)
```
Then, use those data structures and a `while` loop to implement the crawling logic:
```
' current iteration
Dim i As Integer = 1
' the maximum number of pages to scrape
Dim limit As Integer = 5
' until there are no pages to scrape
' or the limit is hit
While pagesToScrape.Count <> 0 AndAlso i < limit
' get the current page to scrape
Dim currentPage = pagesToScrape.Dequeue()
' load the page
Dim document = web.Load(currentPage)
' select the pagination links
Dim paginationHTMLElements = document.DocumentNode.QuerySelectorAll("a.page-numbers")
' logic to avoid visiting a page twice
If paginationHTMLElements IsNot Nothing Then
For Each paginationHTMLElement In paginationHTMLElements
' extracting the current pagination URL
Dim newPaginationLink = paginationHTMLElement.Attributes("href").Value
' if the page discovered is new
If Not pagesDiscovered.Contains(newPaginationLink) Then
' if the page discovered needs to be scraped
If Not pagesToScrape.Contains(newPaginationLink) Then
pagesToScrape.Enqueue(newPaginationLink)
End If
pagesDiscovered.Add(newPaginationLink)
End If
Next
End If
' scraping logic
' increment the counter
i += 1
End While
```
Integrate the above snippet into `Program.vb`, and you'll get:
```
Imports HtmlAgilityPack
Imports CsvHelper
Imports System.Globalization
Imports System.IO
Public Module Program
' define a custom class for the data to scrape
Public Class Product
Public Property Url As String
Public Property Image As String
Public Property Name As String
Public Property Price As String
End Class
Public Sub Main()
' initialize the HAP HTTP client
Dim web As New HtmlWeb()
' where to store the scraped data
Dim products As New List(Of Product)()
' the URL of the first pagination web page to scrape
Dim firstPageToScrape = "https://www.scrapingcourse.com/ecommerce/page/1/"
' the list of pages discovered with the crawling logic
Dim pagesDiscovered As New HashSet(Of String) From {firstPageToScrape}
' the list of pages that still need to be scraped
Dim pagesToScrape As New Queue(Of String)()
pagesToScrape.Enqueue(firstPageToScrape)
' current iteration
Dim i As Integer = 1
' the maximum number of pages to scrape
Dim limit As Integer = 5
' until there are no pages to scrape
' or the limit is hit
While pagesToScrape.Count <> 0 AndAlso i < limit
' get the current page to scrape
Dim currentPage = pagesToScrape.Dequeue()
' load the page
Dim document = web.Load(currentPage)
' select the pagination links
Dim paginationHTMLElements = document.DocumentNode.QuerySelectorAll("a.page-numbers")
' logic to avoid visiting a page twice
If paginationHTMLElements IsNot Nothing Then
For Each paginationHTMLElement In paginationHTMLElements
' extracting the current pagination URL
Dim newPaginationLink = paginationHTMLElement.Attributes("href").Value
' if the page discovered is new
If Not pagesDiscovered.Contains(newPaginationLink) Then
' if the page discovered needs to be scraped
If Not pagesToScrape.Contains(newPaginationLink) Then
pagesToScrape.Enqueue(newPaginationLink)
End If
pagesDiscovered.Add(newPaginationLink)
End If
Next
End If
' select all HTML product nodes
Dim productHTMLElements = document.DocumentNode.QuerySelectorAll("li.product")
' iterate over the list of product HTML elements
For Each productHTMLElement In productHTMLElements
' scraping logic
Dim url = HtmlEntity.DeEntitize(productHTMLElement.QuerySelector("a").Attributes("href").Value)
Dim image = HtmlEntity.DeEntitize(productHTMLElement.QuerySelector("img").Attributes("src").Value)
Dim name = HtmlEntity.DeEntitize(productHTMLElement.QuerySelector("h2").InnerText)
Dim price = HtmlEntity.DeEntitize(productHTMLElement.QuerySelector("span").InnerText)
' instantiate a new Product object with the scraped data
' and add it to the list
Dim product = New Product With {
.Url = url,
.Image = image,
.Name = name,
.Price = price
}
products.Add(product)
Next
' increment the counter
i += 1
End While
' export the scraped data to CSV
Using writer As New StreamWriter("products.csv")
Using csv As New CsvWriter(writer, CultureInfo.InvariantCulture)
' populate the CSV file
csv.WriteRecords(products)
End Using
End Using
End Sub
End Module
```
Now, run the program again:
```nginx
dotnet run
```
This time, the script will go through 5 different pagination pages. The new output CSV will then contain more than the 16 records scraped before:
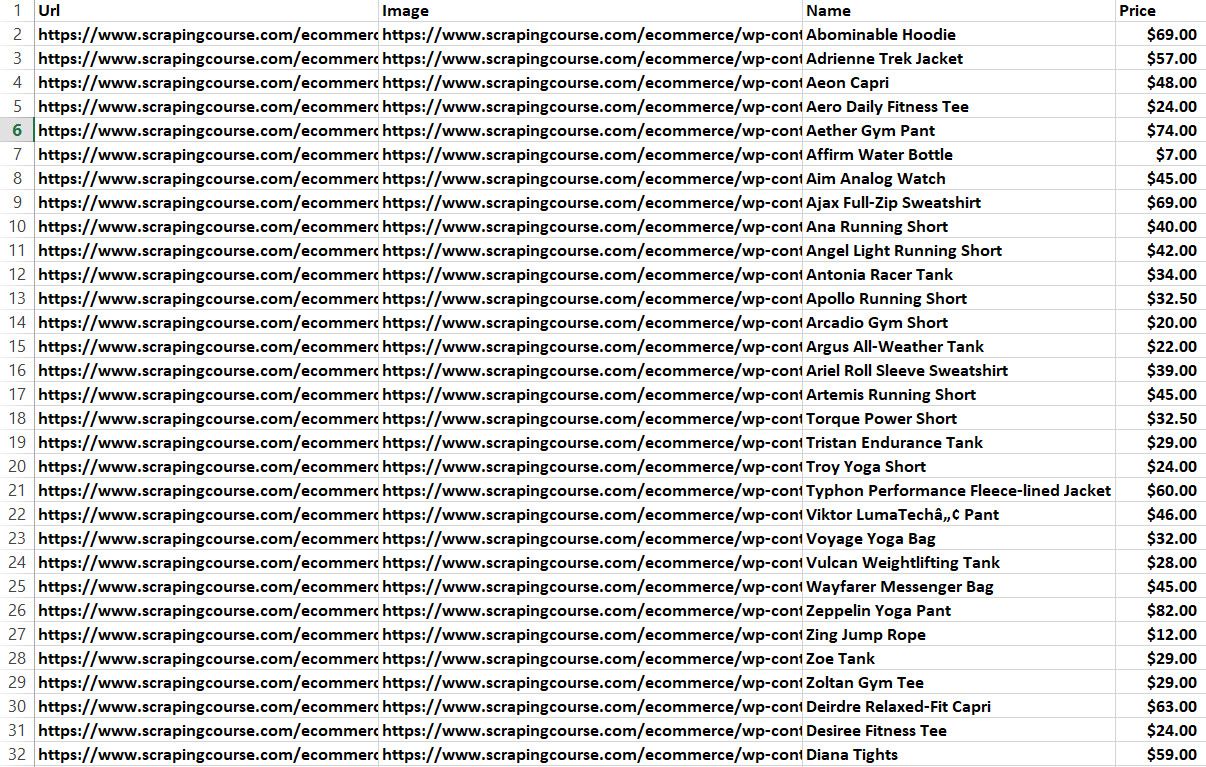
Congrats! You just learned how to perform web crawling and web scraping with Visual Basic!
### Avoid Getting Blocked When Scraping With Visual Basic
Data—even if it's public—is immensely valuable. Here's why most companies protect their sites with anti-bot technologies. These can detect and block automated scripts, such as your script. Those solutions are the biggest challenge to web scraping in Visual Basic.
The two main tips for scraping a site effectively are:
1. Set a real User-Agent.
2. Use a proxy to change your exit IP.
Discover other successful strategies in our guide on [web scraping without getting blocked](/blog/web-scraping-without-getting-blocked).
Follow the instructions below to implement them in Html Agility Pack.
Get the User-Agent set by a real browser and the URL of a proxy from a site like [Free Proxy List](https://free-proxy-list.net/). Configure them in HAP as below:
```
' set the User-Agent header
Dim userAgent As String = "Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/121.0.0.0 Safari/537.36"
web.UserAgent = userAgent
' set a proxy
Dim proxyIP As String = "204.12.6.21"
Dim proxyPort As String = "3246"
Dim proxyUsername = Nothing
Dim proxyPassword = Nothing
Dim document = web.Load("https://www.scrapingcourse.com/ecommerce/", proxyIP, proxyPort, proxyUsername, proxyPassword)
```
This way, you're making your request appear to come from a browser while protecting your IP.
> **Info**
>
> By the time you read this tutorial, that proxy server will no longer work. That's because free proxies are short-lived and unreliable. Harness them for learning purposes only, but forget about using them in production!
Thanks to those two tips, you can avoid most simple bypass anti-bot measures. Will that be enough against advanced solutions such as [Cloudflare](/blog/bypass-cloudflare)? Definitely not! A complete [WAF](/blog/waf-bypass) like that can still easily detect your Visual Basic web scraping script as a bot.
Verify that isn't enough by targeting a Cloudflare-protected site like G2:
```
Imports HtmlAgilityPack
Imports System.Net
Public Module Program
Public Sub Main()
' initialize the HAP HTTP client
Dim web As New HtmlWeb()
' set the User-Agent header
Dim userAgent As String = "Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/121.0.0.0 Safari/537.36"
web.UserAgent = userAgent
' set a proxy
Dim proxyIP As String = "204.12.6.21"
Dim proxyPort As String = "3246"
Dim proxyUsername = Nothing
Dim proxyPassword = Nothing
Dim document = web.Load("https://www.g2.com/products/notion/reviews", proxyIP, proxyPort, proxyUsername, proxyPassword)
' print the HTML source code
Console.WriteLine(document.DocumentNode.OuterHtml)
End Sub
End Module
```
The result will be the following `403 Forbidden` HTML page containing a CAPTCHA:
```nginx
Just a moment...
```
Time to give up? Not at all! You only need the right tool, and its name is [Zenrows](/)! This next-generation scraping API provides the best anti-bot toolkit and supports User-Agent and IP rotation. These are just a few of the dozens of features the tool offers.
Give your Visual Basic scraping script superpowers through Zenrows! [Sign up for free](/) to redeem your first 1,000 credits and reach the Request Builder page:
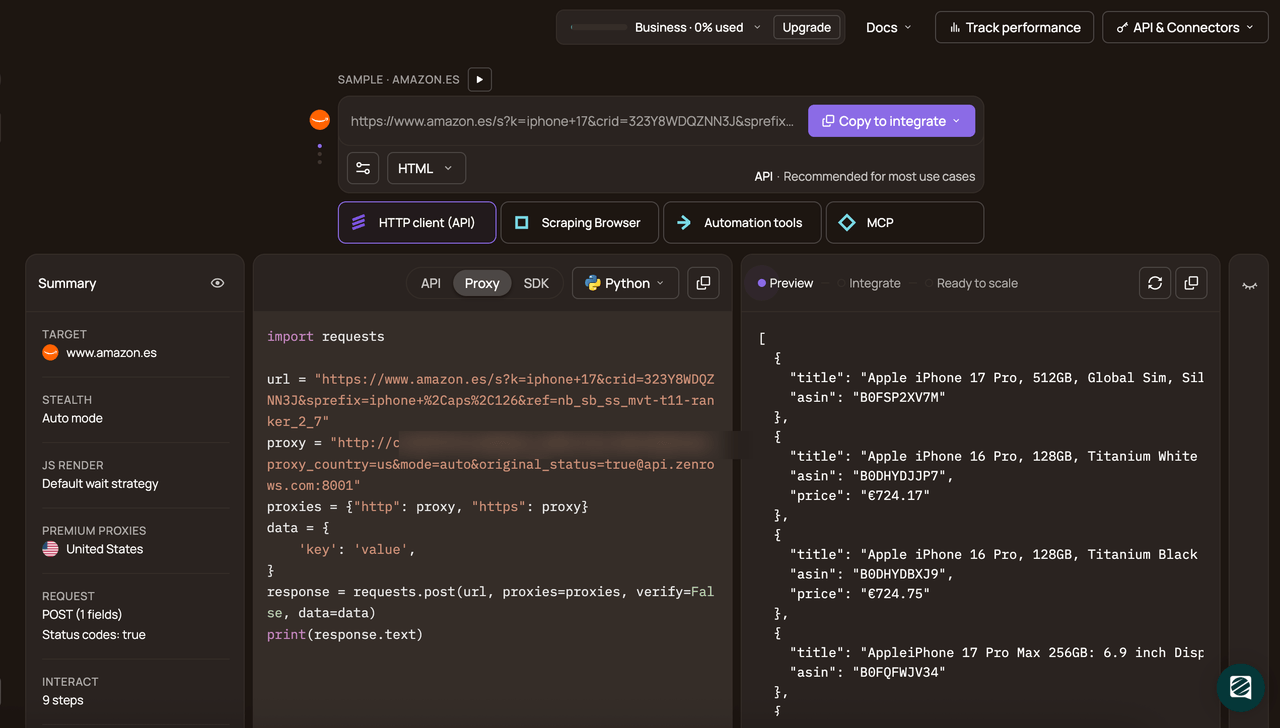
Here, suppose you want to scrape the [page protected with G2.com page mentioned earlier](https://www.g2.com/products/notion/reviews):
1. Paste the target URL (`https://www.g2.com/products/notion/reviews`) into the "URL to Scrape" input.
2. Enable the "JS Rendering" mode (the User-Agent rotation and AI-powered anti-bot toolkit are always included by default).
3. Toggle the "Premium Proxy" check to get rotating IPs.
4. Select “cURL” and then the “API” mode to get the URL of the Zenrows API to call in your script. With Zenrows, it's easy to [bypass anti-bots like Cloudflare with cURL](/blog/curl-bypass-cloudflare).
Use the generated URL in the HAP `Load()` method:
```
Imports HtmlAgilityPack
Imports System.Net
Public Module Program
Public Sub Main()
' initialize the HAP HTTP client
Dim web As New HtmlWeb()
' connect to target page
Dim document = web.Load("https://api.zenrows.com/v1/?apikey=&url=https%3A%2F%2Fwww.g2.com%2Fproducts%2Fnotion%2Freviews&js_render=true&premium_proxy=true")
' print the HTML source code
Console.WriteLine(document.DocumentNode.OuterHtml)
End Sub
End Module
```
Launch the script, and this time it'll print the HTML associated with the target G2 page as desired:
```nginx
Notion Reviews 2024: Details, Pricing, & Features | G2
```
Wow! Bye-bye 403 errors. You just saw how easy it is to use Zenrows for web scraping with Visual Basic.
### Use a Headless Browser With Visual Basic
HAP is primarily an HTML parser. Although the library supports browser rendering, this functionality is unavailable in .NET. If you want to scrape pages that use JavaScript execution, you need another tool.
Specifically, you have to use a tool that can render pages in a browser. One of the most up-to-date and popular headless .NET browser libraries is [Puppeteer Sharp](https://www.puppeteersharp.com/).
Install it via the Nuget [`PuppeteerSharp`](https://www.nuget.org/packages/PuppeteerSharp/) package with this command:
```nginx
dotnet add package PuppeteerSharp
```
To learn more about what this library offers, see our dedicated tutorial on [`PuppeteerSharp`](/blog/puppeteersharp).
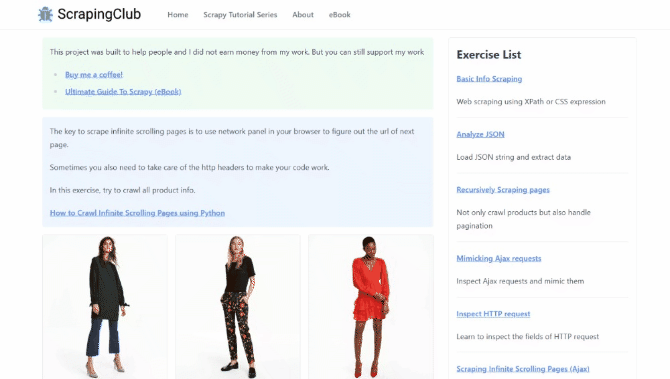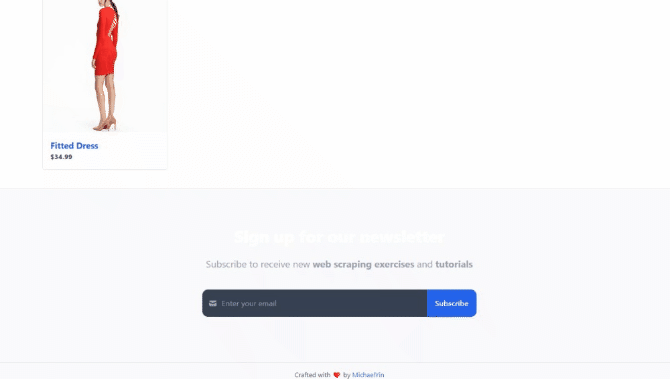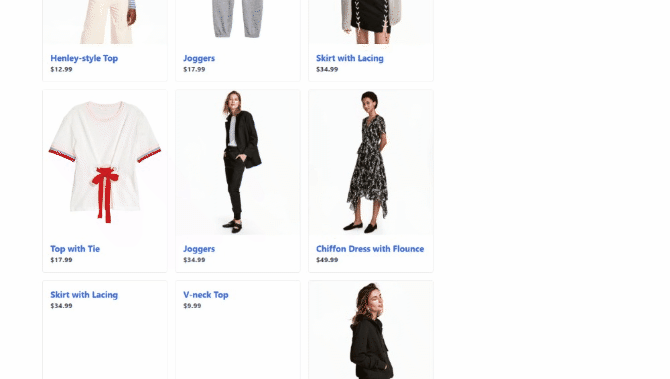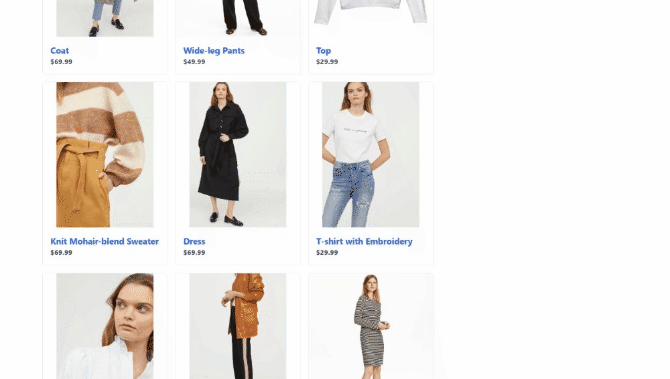
To better showcase Puppeteer in C#, we need to change the target page. Let’s target a page that depends on JavaScript, such as the [Infinite Scrolling demo](https://scrapingclub.com/exercise/list_infinite_scroll/). This dynamically loads new data as the user scrolls down:
Use PuppeteerSharp to scrape data from a dynamic content page in Visual Basic as follows:
```
Imports PuppeteerSharp
Module Program
Public Sub Main()
Scrape.Wait()
End Sub
Private Async Function Scrape() As Task
' download the browser executable
Await New BrowserFetcher().DownloadAsync()
' browser execution configs
Dim launchOptions = New LaunchOptions With {
.Headless = True ' = False for testing
}
' open a new page in the controlled browser
Using browser = Await Puppeteer.LaunchAsync(launchOptions)
Using page = Await browser.NewPageAsync()
' visit the target page
Await page.GoToAsync("https://scrapingclub.com/exercise/list_infinite_scroll/")
' select all product HTML elements
Dim productElements = Await page.QuerySelectorAllAsync(".post")
' iterate over them and extract the desired data
For Each productElement In productElements
' select the name and price elements
Dim nameElement = Await productElement.QuerySelectorAsync("h4")
Dim priceElement = Await productElement.QuerySelectorAsync("h5")
' extract their data
Dim name = (Await nameElement.GetPropertyAsync("innerText")).RemoteObject.Value.ToString()
Dim price = (Await priceElement.GetPropertyAsync("innerText")).RemoteObject.Value.ToString()
'print it
Console.WriteLine("Product Name: " & name)
Console.WriteLine("Product Price: " & price)
Console.WriteLine()
Next
End Using
End Using
End Function
End Module
```
Run this script:
```nginx
dotnet run
```
That's what it'll produce:
```nginx
Product Name: Short Dress
Product Price: $24.99
' omitted for brevity...
Product Name: Fitted Dress
Product Price: $34.99
```
Yes! You're now a Visual Basic web scraping master!
## Conclusion
This step-by-step tutorial guided you through web scraping with Visual Basic. Through it, you began with the fundamentals and saw more complex aspects.
Thanks to the .NET ecosystem, you can access many libraries to extract data from the Web. This means that you can use the well-known Html Agility Pack to do web scraping and crawling in Visual Basic. Plus, you have access to PuppeteerSharp to deal with sites that use JavaScript.
The problem? No matter how good your Visual Basic scraper is, anti-scraping measures can stop it. Avoid them all with [Zenrows](/), a scraping API with the most effective built-in anti-bot bypass features. Scraping data from any web page is only one API call away!